Written by: Doug Camplejohn, CEO & Co-Founder, Coffee
Key Takeaways For Reducing Manual Entry
- Manual data entry reduction spans four separate problems that different layers of the sales stack solve.
- Sales reps spend 17% of their time on manual data entry and CRM management, leaving only 35% for selling.
- Four automation mechanisms, auto-capture activities, data enrichment, browser extensions, and two-way CRM sync, each remove specific manual tasks.
- Judgment fields such as deal-stage decisions and qualification nuance still require human context.
- Coffee acts as the agent layer that writes enriched, deduplicated records into Salesforce or HubSpot without human entry.
See How Coffee Automates Your CRM
Readiness And Preconditions Before You Evaluate Tools
Teams see better results when they confirm four basics before evaluating any tool.
- Which CRM you run, Salesforce or HubSpot, and which objects and required fields govern your pipeline
- Who owns data quality and has authority to change field configurations
- What your current field-completion rate looks like on active deals
- Whether your existing records are deduplicated, because enriching duplicate records consumes credits and creates conflicting values that break reporting
Set expectations early. The goal is to move hours away from reps and into automation, not erase every manual touch. Judgment fields with no external signal remain manual by design, regardless of the automation layer you deploy.
Check Coffee’s Fit For Your Stack
Step 1: Map Your Current Manual Entry Workflow
With those preconditions in place, start by identifying every field a rep touches today. The inventory should cover contact creation, company records, activity logging, deal stage, call notes, and next steps. Separate structured fields such as picklists, dates, and currency amounts from unstructured fields such as call notes and qualification nuance, because automation handles them differently.

Run this exercise for one week using a CRM field export. The output is a ranked list of every manual entry point by frequency. This list becomes the prioritization framework for every automation decision that follows.
Most missing CRM fields are not missing information in the business. They are details that already exist elsewhere in transcripts, email threads, quoting tools, and signature blocks that no one has copied over. The audit shows where the data lives, not just where it is absent.
Step 2: Separate The Four Mechanisms That Eliminate Manual Entry
Four core mechanisms remove different types of manual work, and each one operates at a different layer of the stack.
Auto-Capture Activities
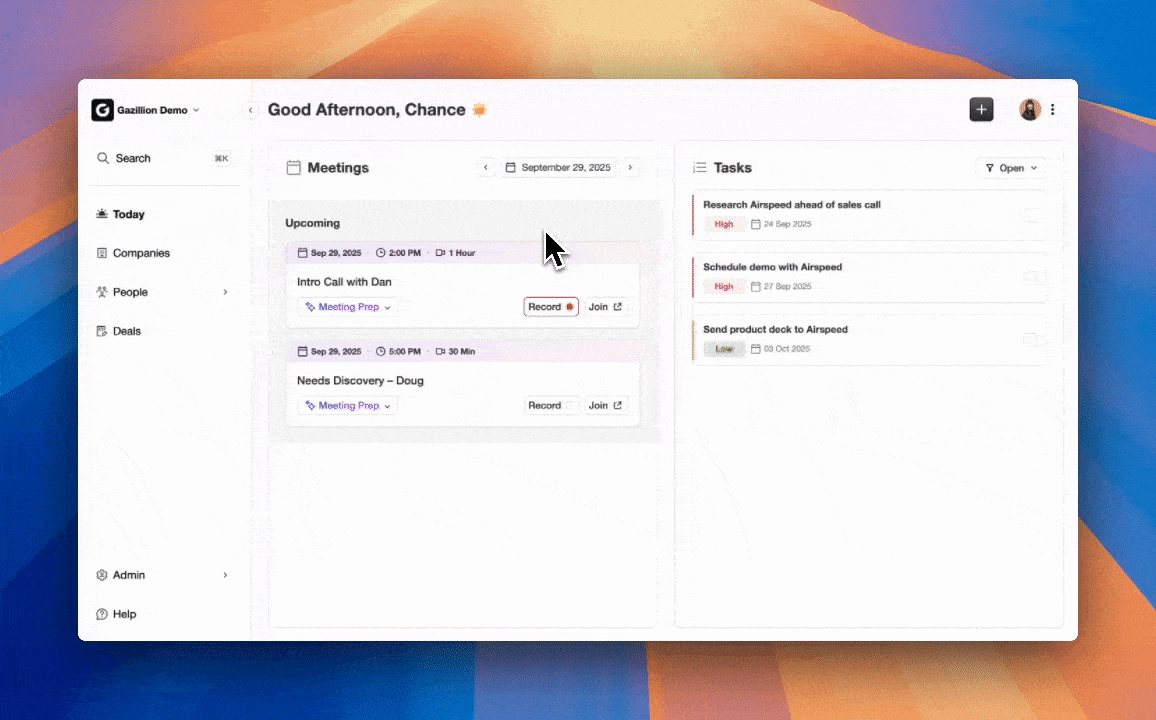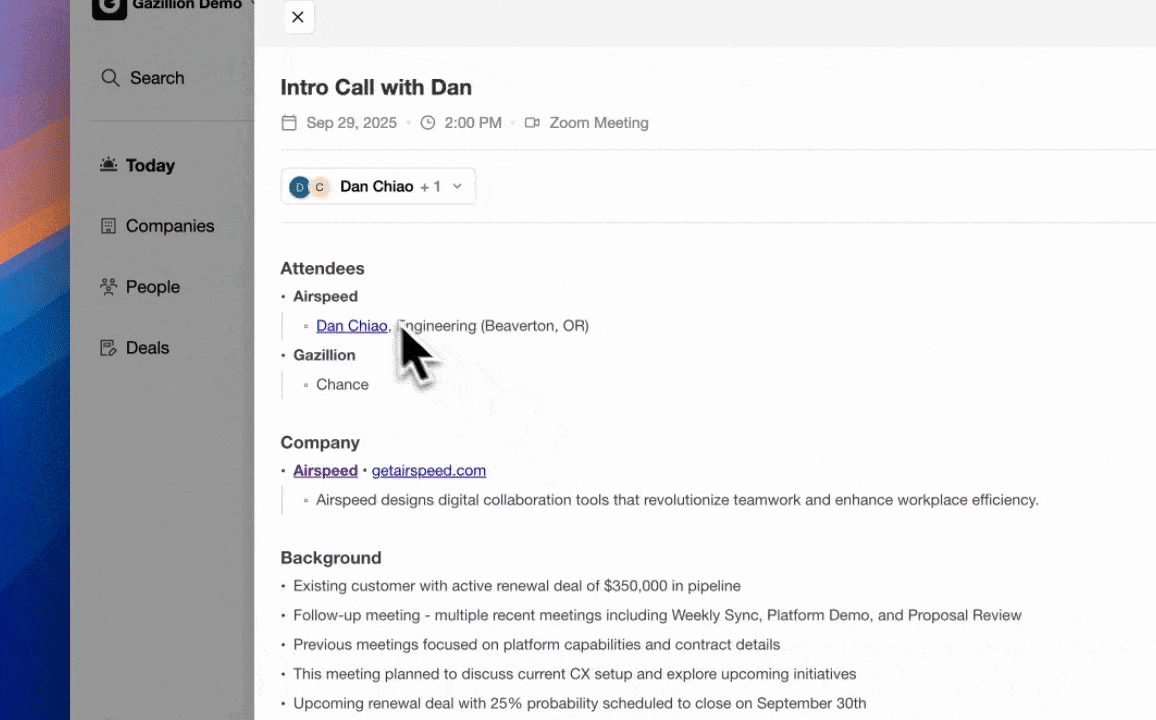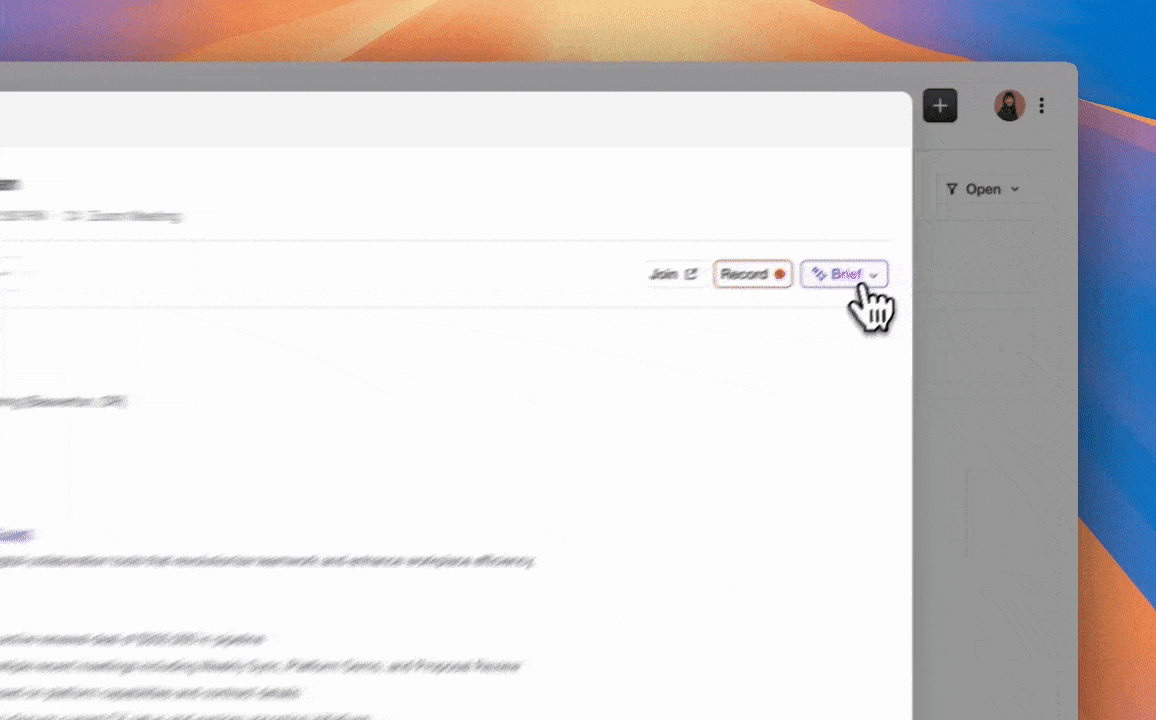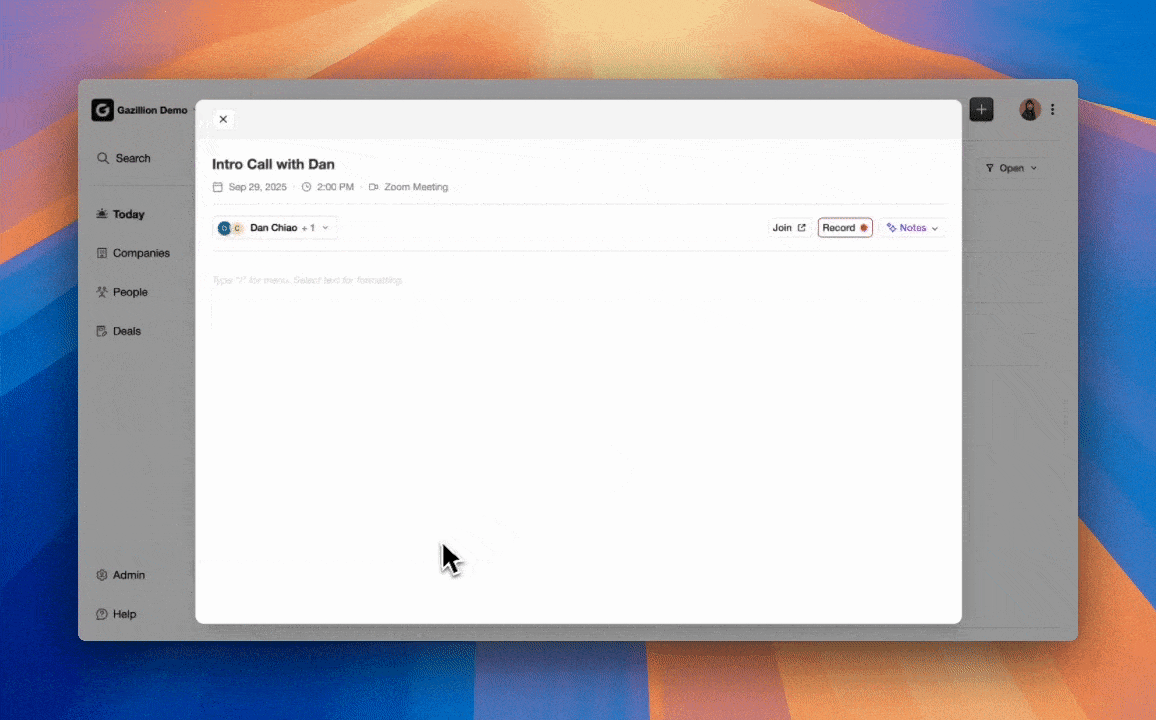
Auto-capture logs email opens, replies, calls, and meetings without rep input. Connecting Gmail or Outlook auto-logs sent and received emails, meeting invites, and call activities to the relevant contact, company, and deal records without the rep opening the CRM. Both HubSpot Sales Hub and Salesforce Einstein Activity Capture provide native email and calendar auto-logging at no extra cost. This makes auto-capture the fastest and cheapest mechanism to deploy. Native auto-logging records that activity happened, but it does not convert conversations into structured deal fields.
Data Enrichment
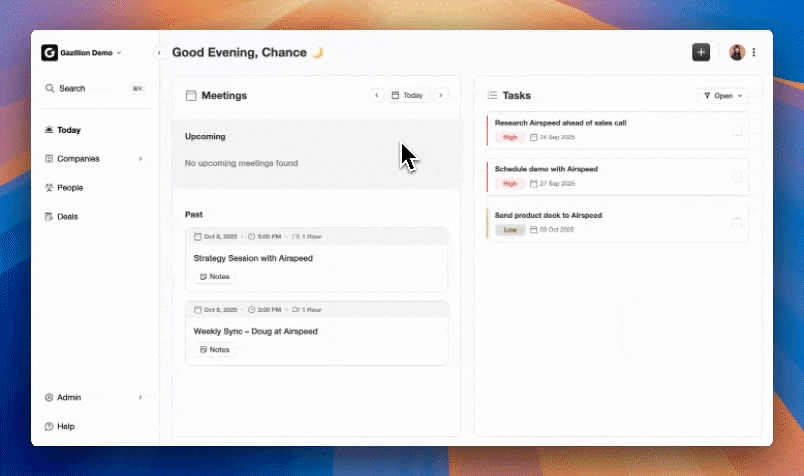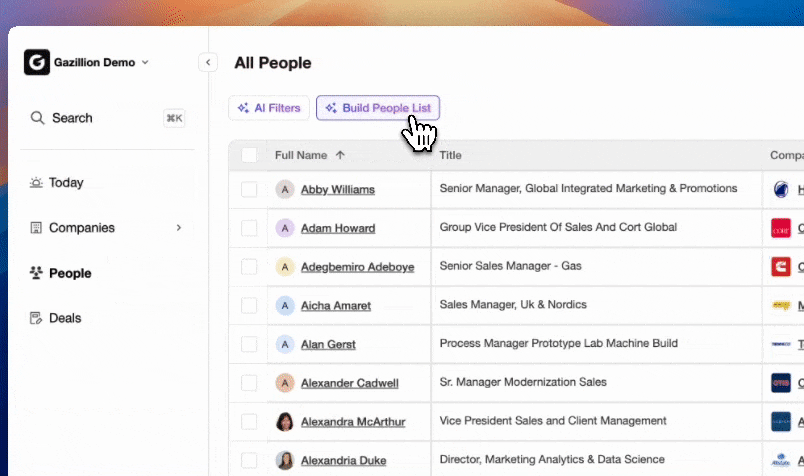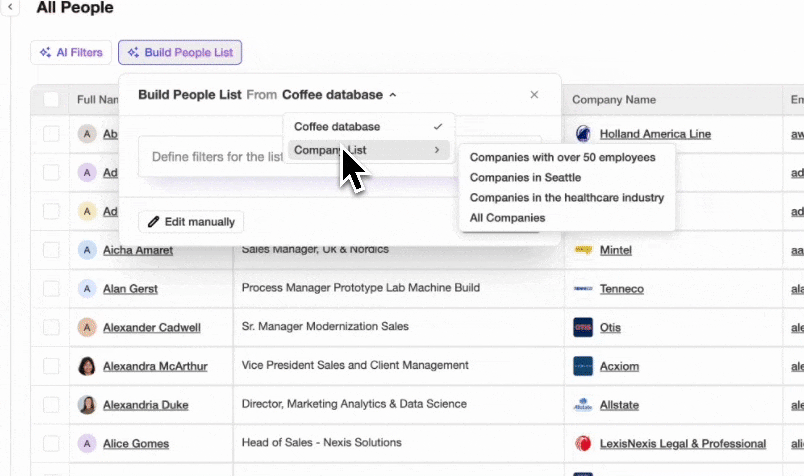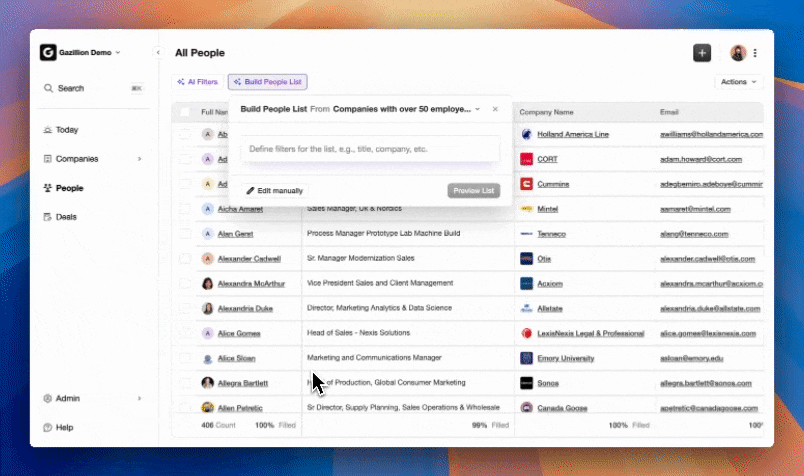
Enrichment tools append job titles, emails, phone numbers, and company information so profiles fill in without rep effort. HubSpot’s enrichment layer automatically populates over 40 contact and company properties, including industry, company size, annual revenue, location, job title, and social media profiles, keyed off work email and company domain. Coffee’s agent performs the same function natively. It augments records with job titles, funding data, and LinkedIn profiles via licensed data partners, which removes the need for a separate tool like Apollo.io or ZoomInfo.
Browser Extensions
Browser-based lead clippers pull prospect data directly from web pages and professional networks with a click. LeadIQ’s Chrome extension lets reps push a LinkedIn contact directly to Salesforce or HubSpot with Outreach or Salesloft sequence enrollment triggered in the same action. This completes the handoff from prospecting research to CRM to outreach sequence in a few clicks without switching tabs. Browser extensions still depend on rep-initiated action and do not maintain records continuously.
Two-Way CRM Sync
Two-way sync moves prospect lists, status updates, and pipeline stages into the main database without copy-pasting. Two-way CRM sync keeps contact records updated automatically and deal stages reflecting real activity, so when a rep picks up a conversation mid-sequence the full history is already in the CRM. Shallow CRM syncs, where contacts sync only once rather than continuously, break quickly and force reps to double-check records before every outreach motion.
Step 3: Run A Field-By-Field Teardown
The key question in any automation evaluation is which specific fields a tool eliminates and which ones stay manual. The table below maps each field to its automation layer and shows the pattern: mechanical fields are fully automated, firmographic fields are enriched, and judgment fields remain human-required.
| Field | Automated | Enriched | Human-Required |
|---|---|---|---|
| Contact creation | Agent scans email/calendar to auto-create | — | — |
| Company record | Agent creates from email domain | — | — |
| Last activity / next activity | Logged autonomously from email and calendar | — | — |
| Job title | — | Populated from licensed data partners | Override if rep confirmed different title on call |
| Industry / firmographics | — | Populated from enrichment providers | — |
| Funding / company size | — | Populated from enrichment providers | — |
| LinkedIn profile | — | Appended via licensed data | — |
| Call notes (structured) | AI meeting bot transcribes and summarizes | — | Rep reviews and confirms |
| Deal-stage decision | — | — | Rep judgment required |
| Qualification nuance (BANT, MEDDIC) | AI extracts signals from transcript | — | Rep confirms accuracy |
| Custom fields (internal strategy) | — | — | Rep or RevOps required |
| Forecast category (gut-feel) | — | — | Human by design, no external signal exists |
List the residual manual work explicitly. Judgment fields with no external signal, such as a gut-feel forecast category or a qualification score based on internal strategy, remain manual by design.
Required-Field Policies Backfire. 37% of sales reps admit to entering inaccurate data to satisfy required fields they do not understand, filling them with placeholders like “Unknown” or “TBD” to clear the validation wall. A CRM with five well-chosen required fields that reps complete accurately produces better data than one with twenty required fields completed minimally.
Step 4: Decide Where The Automation Should Live
The decision framework centers on three layers. Each layer eliminates different work, leaves different gaps, and the comparison shows why only the agent layer closes the record-hygiene gap.
| Layer | What It Eliminates | What It Leaves Behind |
|---|---|---|
| Prospecting Database (Apollo.io, ZoomInfo) | Manual list-building; contact discovery | Record hygiene, the record still depends on someone maintaining it after the list is built |
| CRM-Native Automation (HubSpot, Salesforce) | Activity logging; basic enrichment at form fill | Deal-critical facts that never get typed, native rules only fire on data already inside the CRM |
| Agent Layer (Coffee) | Contact creation, enrichment, activity logging, deduplication, written directly to Salesforce or HubSpot without human entry | Judgment fields; deal-stage decisions; qualification nuance |
Prospecting databases provide lists and contact discovery, while record hygiene still depends on ongoing maintenance. Apollo.io’s enterprise Salesforce integration lacks the custom object support and deduplication sophistication needed for teams with highly customized Salesforce instances. CRM-native automation depends on humans entering data first, so it cannot capture deal-critical facts that never get typed. An agent layer writes enriched, deduplicated records back into Salesforce or HubSpot without human entry and closes the gap the other two layers leave open.
Beyond these three layers, newer alternatives like Day.ai and Clarify lack deep understanding of Salesforce and HubSpot integration complexity, including quotas, forecasting, required fields, and custom objects. That gap creates problems for teams of any size running established CRM instances.
Step 5: Evaluate Integration Depth For Your Specific CRM
Both Salesforce and HubSpot expose the APIs automation tools write to, and the practical difference between tools is mapping depth. The key question is whether the tool can write to custom fields and set picklist values that already exist in the instance, or only push standard fields and notes.
HubSpot’s native email and calendar sync auto-logs activity at no extra cost but does not convert conversations into structured deal fields. Salesforce’s Einstein Activity Capture behaves similarly. Both features serve as starting points rather than complete automation.
For Salesforce users, relevant complexity includes required fields, forecasting objects, quotas, and custom objects. For HubSpot users, the contact and company object model governs how enrichment lands and how lifecycle stages propagate. An agent layer that understands this complexity is the difference between automation that holds and automation that breaks. Treating both CRMs as generic API endpoints leads to automation that fails on the first required-field validation error.
Shallow Syncs Break Fast. Shallow CRM syncs that sync contacts once rather than continuously break quickly and force reps to double-check records before every outreach motion. That pattern recreates the manual verification work the tool was supposed to eliminate.
Step 6: Set Data-Quality Guardrails
Enrichment that contradicts rep knowledge erodes CRM trust faster than no enrichment at all. Three guardrails keep enrichment helpful instead of harmful.
Run Deduplication Before Enrichment. Automated enrichment can create duplicate CRM records when deduplication is not run before the enrichment job. This splits engagement history and enriched data across ghost records. Versium recommends a duplicate record rate of 2% or less as the pass threshold for CRM import, with 2–5% triggering a review of resolution logic.
Write Enriched Values Only To Empty Fields. HubSpot recommends configuring enrichment in “enrich only empty fields” mode so that manually verified data, such as a rep-confirmed direct line, a negotiated deal value, or a custom property set by RevOps, does not get overwritten by automated enrichment that may be outdated.
Route Low-Confidence Matches To Human Review. Versium recommends a minimum enrichment match confidence score of 0.75 before CRM import, with records scoring 0.5–0.74 queued for manual review and records below 0.5 discarded or re-enriched with an alternate identifier.
Together, these three guardrails keep enrichment from eroding the trust that makes the CRM worth maintaining.
Step 7: Staff Around The Residual Manual Work
No tool eliminates all manual entry. Assigning ownership of the residual work keeps it from defaulting back to reps by accident.
- RevOps owns: data quality governance, field schema, deduplication cadence, enrichment configuration, and field-completion monitoring
- Reps own: deal-stage judgment, qualification nuance, call-note interpretation, and any field that depends on context only the rep holds
Ownership alone does not keep manual work from creeping back in, because new fields and new processes quietly reintroduce manual entry. Re-run the manual-entry inventory quarterly to catch what has crept back in. What the agent handles at launch may not cover what the team adds in month four.
How To Verify The Process Is Working
Four simple metrics show whether the new workflow actually reduces manual entry.
- Field-completion rate on active deals should climb toward 100% without reminders. Flat rates signal that automation is not mapped to the fields the team forecasts on.
- Duplicate-record count should trend down week over week. Any upward trend signals resolution logic drift.
- Rep time spent on data entry should fall based on self-reported hours. If it does not, the highest-frequency entry points remain manual.
- Pipeline review accuracy should improve, with forecast calls requiring less manual reconciliation as field completeness rises.
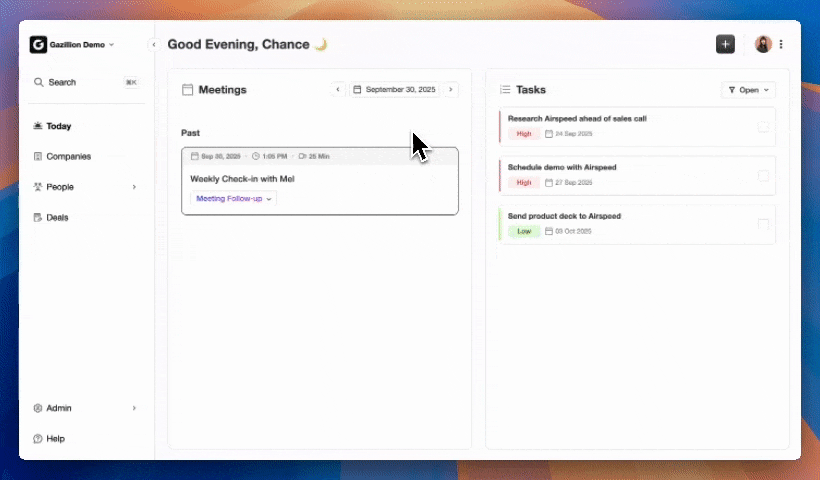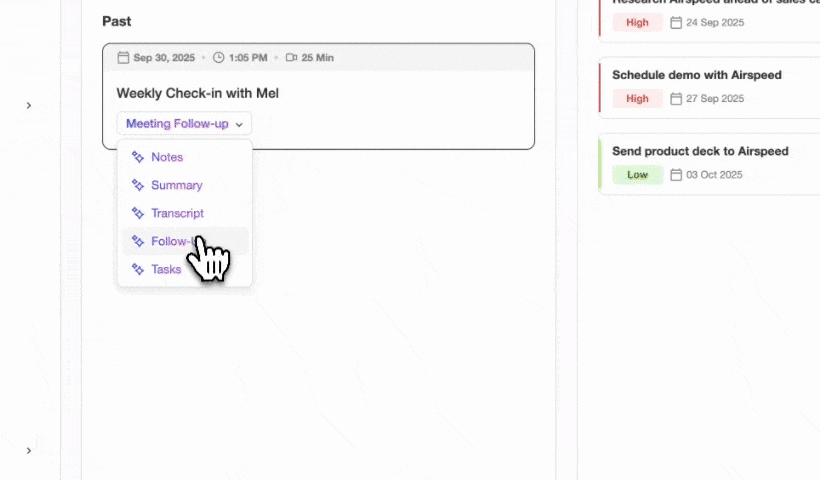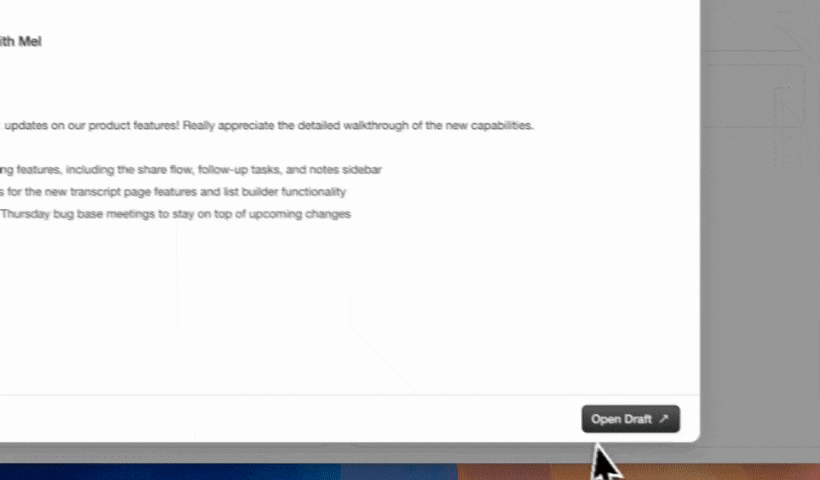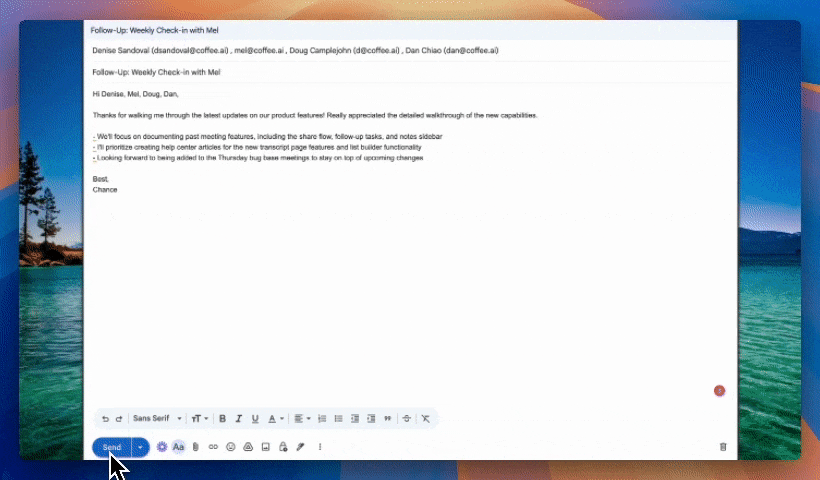
Coffee’s Pipeline Compare feature visualizes week-over-week changes without spreadsheets, turning pipeline reviews from interrogation sessions into strategic discussions. Because the Coffee Agent captures history in a built-in data warehouse, the output stays current rather than reflecting a snapshot from the last time a rep updated a stage.
Track Your Pipeline Automatically With Coffee
Scaling The Workflow For SMBs And Mid-Market Teams
The same framework applies at every team size, but the implementation path shifts with CRM maturity.
Teams on spreadsheets or lightweight CRMs, typically founders and early hires at companies with 1 to 20 employees, need a system of record that handles data entry from day one. They do not benefit from a tool layered on top of a passive database. Coffee’s Standalone CRM deploys the agent as the entire platform, so the CRM never becomes a chore that requires human maintenance to stay accurate.
Teams committed to Salesforce or HubSpot, such as RevOps leads and Heads of Sales at 40-person SaaS companies, need an agent layer on top of the existing system of record. Coffee’s Companion App deploys the Coffee Agent as an intelligent layer on top of an existing Salesforce or HubSpot installation. It handles the “data in” process so the system of record stays accurate without human effort. A simple authentication allows the Coffee Agent to sync data, enrich it, and write valuable insights back to the primary CRM.
Coffee’s dual-model strategy reframes the decision. Teams do not have to choose between replacing Salesforce and staying stuck. They can add the agent layer that closes the gap their current stack leaves open.
Frequently Asked Questions About Manual Data Entry And AI
How Do You Reduce Manual Data Entry Errors?
The guardrails in Step 6, deduplication before enrichment, empty-field-only writes, and human review for low-confidence matches, are the starting point. Required-field policies that force reps to enter placeholder values like “Unknown” or “TBD” produce technically present but useless data. The real fix connects the CRM to where the deal information already exists and removes the manual step. Field design that uses picklists for finite valid values, rather than free text, prevents the most common normalization failures before they reach the deduplication layer.
Will Data Entry Be Replaced By AI?
AI eliminates the mechanical layer of data entry, including activity logging, contact creation, firmographic enrichment, and call summarization. These tasks are high-frequency and low-judgment, which makes automation reliable and durable. Judgment fields with no external signal, such as a gut-feel forecast category, a qualification score based on internal strategy, or a deal-stage decision that depends on relationship context, remain manual by design. AI replaces clerk work and returns judgment work to the rep, which creates the right division of labor.
What Manual Data Entry Can Prospecting Software Not Eliminate?
Call-note judgment, deal-stage decisions, custom fields tied to internal strategy, and qualification nuance still require a human, because they depend on context no system can infer from an email or a transcript. The procurement contact who appeared in a CC line in week three, the competitor named once in a reply, and the verbal agreement to start next fiscal quarter all illustrate this gap. Prospecting software can surface the signals, and the rep interprets what they mean for a specific deal.
How Do You Prevent Automation From Creating Duplicate Records In Salesforce Or HubSpot?
Prevention starts with a single system of record for contacts and companies. Run deduplication before any enrichment job, and configure the tool to update existing records rather than create new ones. In Salesforce, configure matching rules and duplicate rules to warn or block duplicate creation during manual entry and imports. In HubSpot, use the Manage Duplicates tool to flag likely matches by email, name, and company before running bulk enrichment. Treat deduplication as a recurring governance task rather than a one-time cleanup, because duplicates enter a CRM continuously through form submissions, list imports, integration syncs, and manual data entry.
How Does An Agent Layer Differ From A Prospecting Database?
A prospecting database provides lists to work from, while an agent layer writes enriched, deduplicated records back into your CRM without human entry so the record stays current after the list is built. The distinction matters because a prospecting database solves the discovery problem, finding the right contacts, and an agent layer solves the hygiene problem, keeping those contacts accurate, associated with the right company records, and connected to the activity history that makes pipeline reviews reliable. Apollo.io syncs contacts into Salesforce and HubSpot, but CRM record ownership depends on someone maintaining linked personal CRM credentials, otherwise records are assigned to the team sync user or the highest-permission authenticated user. An agent layer removes that dependency.
Conclusion: Close The Remaining Gap
The process is sequential: map your current manual entry workflow, separate the four mechanisms, run the field-by-field teardown, decide where automation should live, evaluate integration depth for your CRM, set data-quality guardrails, and staff around the residual work no tool eliminates. Each step narrows the gap between what automation handles and what still lands on a rep’s plate.
The gap that remains after prospecting databases and CRM-native automation have done their work is the one an agent layer closes. Coffee is that agent layer. As a Companion App, it writes enriched, deduplicated records into Salesforce or HubSpot without human entry, handling contact creation, activity logging, enrichment, and meeting intelligence so reps stop acting as data entry clerks. As a Standalone CRM, it serves as the system of record for teams that have outgrown spreadsheets but do not want to inherit 25 years of legacy architecture. In both models, the agent does the work and the rep does the selling.
Start Your Free Trial Of Coffee