Written by: Doug Camplejohn, CEO & Co-Founder, Coffee | Last updated: August 15, 2026
Key Takeaways
- Most B2B visitor-ID tools, including Warmly, identify 5–20% of US visitors at the person level and 30–65% at the company level.
- Standalone platforms usually send raw lists or Slack alerts, then rely on manual routing, extra tools, and custom setup to create CRM-ready pipeline.
- Teams struggle with duplicate CRM records, weak buyer-persona filters, and manual stitching between identification and outreach.
- Coffee combines pixel-based identification with persona-based Suggested Leads and direct CRM routing, which removes the manual handoff common with tools like Warmly.
- Teams that want identified visitors to flow straight into automated pipeline without extra tools or manual work can start a free trial.
Warmly Match Rates and Traffic Benchmarks
Warmly performs well in the 2026 Artemis GTM comparison of website visitor identification tools and sits within the benchmark range established by a 2026 study of 1.2M B2B sessions that found 47% company-level and 7% person-level identification.
Those aggregate figures hide large swings by traffic source and region. Direct traffic usually identifies at higher rates than Google Ads traffic, and mobile B2B traffic often identifies at lower rates than desktop. For EU visitors, person-level identification is effectively 0% under GDPR without affirmative opt-in.
For a US-leaning B2B SaaS site, realistic 2026 identification rates typically range from 30–65% at the company level and 5–20% at the person level, depending on traffic mix and first-party data. Warmly’s person-level performance sits toward the upper end of that benchmark. Match rate alone does not determine pipeline impact, because workflow and routing quality decide how many identified visitors become revenue.
Warmly Tracking Script: Step-by-Step Setup
Most visitor-ID systems start with a lightweight JavaScript tracking pixel of about 1–3KB that fires on page load and collects device fingerprint, IP address, cookie IDs, URL, referral source, and session timing data in under 50 milliseconds. Warmly follows the same pattern as other tools in this category.
- Generate a custom pixel script from the Warmly dashboard.
- Paste the script into the
<head>tag of every page on your site, or deploy it through a tag manager such as Google Tag Manager. - Verify installation with Warmly’s checker, which confirms that the pixel fires correctly.
- Allow the pixel to collect IP addresses, device fingerprints, and cookie identifiers on each session.
- Send collected identifiers into a waterfall enrichment flow that queries multiple data providers sequentially and stops at the first verified match.
- After a match, run profile enrichment to add full name, work email, job title, seniority, company details, and LinkedIn URL.
- Surface matched visitors as Slack alerts for sales reps, who then decide how and when to follow up.
What Modern Visitor-ID Systems Do Behind the Scenes
Modern tools combine first-party cookies, device fingerprinting, identity graphs, and email pixel matching with IP data to offset weaker IP accuracy from remote work and shared networks. Match rates vary sharply by source: direct and organic search traffic often identifies at 45–55%, while paid ads and social traffic identify at 25–35% because of personal devices and VPNs.
Why Many Visitor-ID Tools Miss on Pipeline
Roughly 96–98% of B2B visitors leave without filling a form, chatting, or signing up. Visitor identification tools help close that gap, yet most stop at identification and never reach reliable pipeline creation. Several recurring operational issues explain the shortfall.
- Raw lists instead of actionable leads. Many platforms identify companies but do not include individual contact details by default, which forces teams to buy extra tools to reach decision-makers.
- Duplicate CRM records. Real-time pushes on every session create duplicates quickly when records are not batched or deduplicated. Industry analyses show that CRM duplicate rates can be high for companies without active data quality programs.
- No buyer-persona matching. Tools often surface every visitor from a company instead of the two or three people who match your ICP, which forces manual triage before outreach.
- Manual stitching between systems. Common CRM integration failures include weak matching-key strategy, incorrect object mapping, manual pushes that bypass field mapping, and no re-sync after rule changes.
- Slack alerts as the endpoint. A Slack notification does not equal a pipeline record, and without direct CRM routing plus automated follow-up, identified visitors usually fade into ignored alerts.
Industry analyses estimate that sales reps lose about 546 hours and $32,000–$40,000 in productivity per rep each year to bad CRM data. These workflow gaps compound that loss when visitor-ID tools push unvalidated or duplicate records into the system.
Try Coffee’s automated pipeline routing to close the loop from pixel hit to CRM-ready pipeline without manual stitching.
Side-by-Side Comparison: Warmly vs. Integrated Visitor-ID Tools
The following table highlights how each platform turns identified visitors into sales motion, focusing on CRM routing, automation depth, and remaining manual work.
| Tool | Person-Level Match Rate (US B2B, 2026) | Workflow Fit | Automation Depth |
|---|---|---|---|
| Warmly | 5–20% | Slack alerts; CRM sync requires configuration | Alert-based, with manual rep action required |
| RB2B | 8–12% | Slack or email alerts; limited native CRM routing | Alert-based, with no persona filtering |
| Koala | 5–20% | Intent signals sent to CRM; setup required | Intent scoring, with limited outreach automation |
| Coffee | Comparable to category range; 5–20% person-level benchmark for US B2B SaaS | Direct CRM routing, Suggested Leads, Campaigns | Pixel to persona match to automated outreach in one agent |
Strong evaluations weigh feature depth against implementation effort, commercial terms, compliance, and workflow activation into CRM, reps, or automation with low friction. On that basis, standalone alert-based tools demand the most extra work before an identified visitor becomes a pipeline record.
Coffee’s Suggested Leads and Direct CRM Routing
Coffee uses the same pixel and waterfall-enrichment mechanics as other visitor-ID tools, then changes the workflow immediately after identification. You add a single tracking script to the <head> tag of your site, Coffee verifies installation, and the agent starts identifying visitors while inferring name, title, email, LinkedIn profile, pages viewed, time on site, and visit history.
Suggested Leads provide the key difference. Warmly and RB2B surface raw people lists or company-only data, while Coffee applies your buyer persona to recommend the two or three individuals inside each visiting company who most closely match your ICP and shows their LinkedIn profiles for instant outbound. With one click, you add the prospect to Coffee with enrichment pre-filled and ready for a LinkedIn connection request, outbound email, or auto-enrollment into a Campaign for multi-step follow-up.
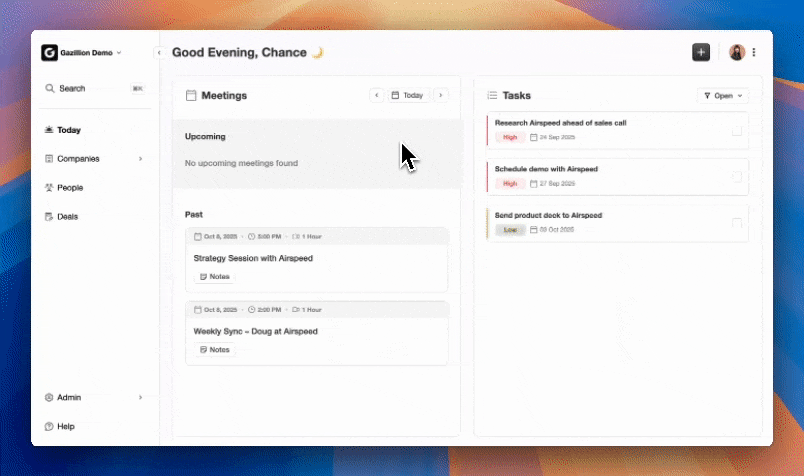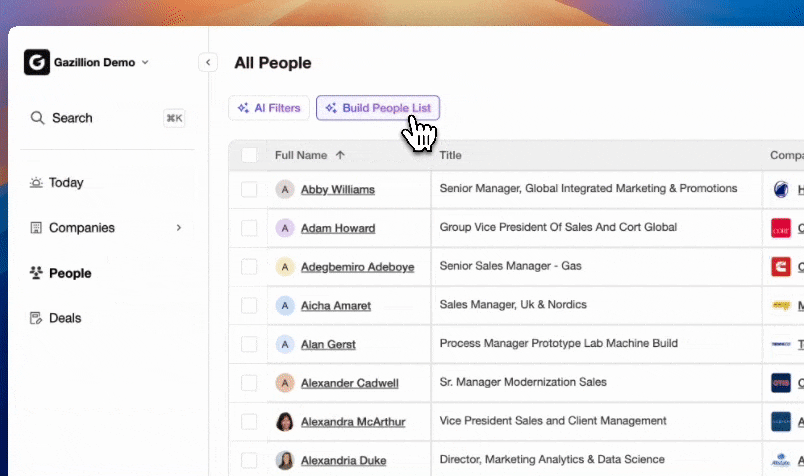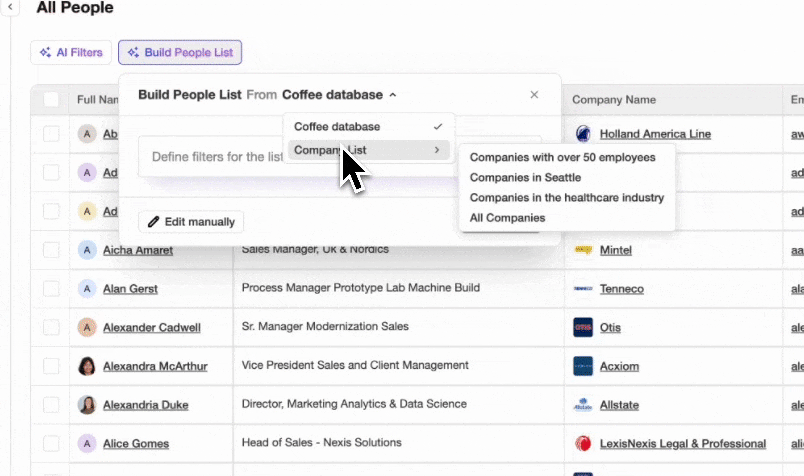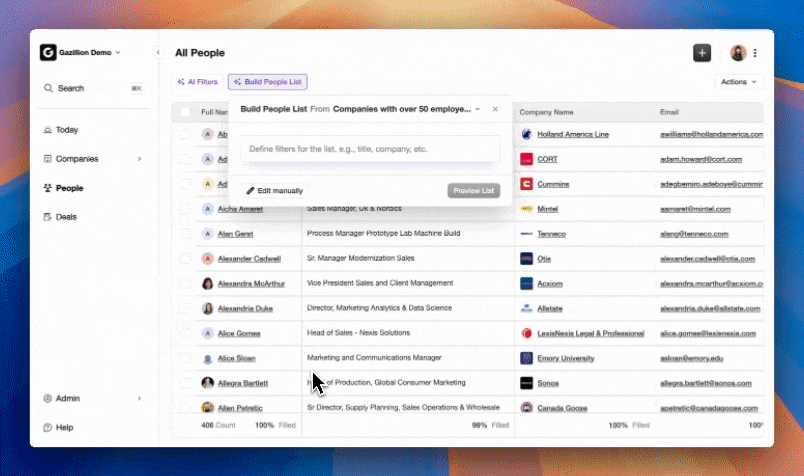
This workflow closes the loop that standalone tools leave open. AI SDRs and agentic outbound systems now consume visitor-ID data at scale, which turns small data errors into high-volume, brand-damaging outreach when inputs are inaccurate. Coffee’s persona-matched Suggested Leads reduce that risk by filtering to the right people before any outreach starts.
Setup Comparison: Coffee vs. Warmly
The table below compares the steps required to move from pixel installation to CRM-ready pipeline and shows where manual configuration or extra tools still enter the process.
| Criteria | Coffee | Warmly | Notes |
|---|---|---|---|
| Pixel installation | Single script in <head>, auto-verified |
Single script in <head>, manual verification |
Both follow standard pixel deployment |
| Primary alert mechanism | Real-time Slack notification plus direct CRM record creation | Slack alerts; CRM sync requires extra configuration | Bi-directional automated data flow usually beats manual export |
| Persona-matched lead selection | Suggested Leads with 2–3 ICP-matched individuals per visiting company | Raw people list from each visiting company | Persona matching reduces manual triage for sales reps |
| Automated outreach | One-click enrollment into Campaigns with multi-step email sequences | Manual rep action after each alert | Coffee removes the gap between identification and outreach |
Best-Fit Guidance by Company Stage
Early-stage teams (10–25 employees, no established CRM). Speed to pipeline matters more than deep integration. Coffee’s Standalone CRM model fits this stage because the pixel, enrichment, Suggested Leads, and Campaigns all run inside one agent without extra subscriptions. Warmly can support early teams, yet it still needs a separate CRM and manual routing to turn alerts into pipeline records.
Established Salesforce or HubSpot teams (25–50 employees). Cleanly feeding the existing system of record becomes the priority, along with avoiding the duplicate-record problem outlined earlier and respecting field-mapping rules. Account-level and person-level identification should use separate CRM workflows and triggers because they resolve to different objects and downstream tools; combining them in one workflow breaks routing and enrichment paths. Coffee’s Companion App deploys as an intelligent layer on top of Salesforce or HubSpot, writes enriched visitor records directly into the system, and lets the agent manage deduplication and field mapping. Warmly’s Slack-alert model at this stage adds a manual handoff that RevOps teams must govern separately.
Explore Coffee’s deployment options whether you need a standalone agent or a companion for your current CRM.
Decision-Framework Checklist
Use these criteria as a sequence to match your constraints to the right visitor-ID tool.
- Confirm match-rate needs. If you require person-level identification above 12%, Warmly and Coffee both sit in the typical 5–20% range for US B2B traffic, while tools below that level, such as RB2B at 8–12%, fit better for company-level intent only.
- Check CRM routing depth. Choose Coffee or another tool with documented bi-directional sync when data freshness matters, and avoid Zapier-only connections for HubSpot or Salesforce if you want low-latency updates.
- Require buyer-persona filtering. Coffee’s Suggested Leads feature is the only option in this comparison that applies persona matching at the identification stage instead of after a raw list lands in your queue.
- Align with budget and subscription count. Warmly usually needs a separate CRM and possibly a separate sequencing tool, while Coffee combines visitor ID, enrichment, CRM, and Campaigns in one seat-based subscription.
- Account for EU traffic share. The GDPR consent requirement discussed earlier removes person-level identification for EU visitors, so you should budget accordingly and focus person-level spend on US traffic.
- Validate compliance posture. Coffee is SOC 2 Type 2 and GDPR compliant. Privacy and compliance controls such as SOC 2 certification and data deletion capabilities now count as standard evaluation criteria for B2B visitor-ID platforms.
- Match tool complexity to team size. Teams under 25 employees without dedicated RevOps should avoid tools that need monthly field-mapping audits. Field mappings and scoring rules for visitor identification require monthly reconciliation because rule changes do not apply retroactively.
See Coffee’s pricing and feature tiers to convert identified visitors into automated pipeline without extra subscriptions or manual stitching.
Frequently Asked Questions
How long does Warmly website visitor identification implementation take?
Installing the Warmly tracking pixel usually takes under 30 minutes. You paste the script into your site’s <head> tag or deploy it through a tag manager, then confirm that it fires correctly. The longer work involves configuring CRM sync, setting Slack alert routing, and defining field-mapping rules so identified visitors land in the right CRM object without creating duplicates. For teams without dedicated RevOps support, that configuration can stretch implementation to one or two weeks. Coffee’s pixel installation follows the same 30-minute process, while the agent handles CRM routing, deduplication, and outreach enrollment automatically, which shortens the time from installation to first pipeline record.
What person-level match rates should I expect in 2026?
For a US-focused B2B SaaS website, you can expect the benchmark range mentioned earlier, with meaningful variation by traffic source. Independent studies show higher identification for direct and organic search traffic than for paid social or display traffic, and desktop sessions usually identify at higher rates than mobile sessions. EU traffic returns effectively no person-level identification without explicit consent, while company-level identification often reaches 30–65% of US B2B sessions depending on the vendor and how aggressively bot and consumer IP traffic are filtered.
How do visitor-ID tools integrate with existing CRMs?
Integration depth varies widely across tools. Some platforms provide native bi-directional sync with Salesforce and HubSpot so that identified visitor records are created, enriched, and updated automatically without manual export. Others connect only through Zapier, which adds latency and demands extra configuration to keep data current. The most common operational failure is a weak or missing matching-key strategy. Without a clear hierarchy, such as exact email match first, then company domain plus name, then domain only, tools push duplicate records into the CRM at high volume. Coffee’s Companion App runs as an agent layer on top of existing Salesforce or HubSpot instances and writes enriched visitor records directly into the system of record while managing deduplication and field mapping natively.
Is website visitor data secure and compliant?
Compliance rules differ by region and identification depth. Company-level IP identification usually falls under legitimate interest in B2B contexts under GDPR, while person-level identification requires explicit consent in GDPR markets, as noted in the match-rate section above. In the US, CCPA and CPRA govern data handling, and person-level identification remains common under those frameworks. When you evaluate any visitor-ID tool, confirm SOC 2 Type 2 certification, documented data deletion capabilities, and whether the vendor uses your data to train shared models. Coffee is SOC 2 Type 2 and GDPR compliant and does not use customer data to train public models.