Written by: Doug Camplejohn, CEO & Co-Founder, Coffee | Last updated: August 25, 2026
Key Takeaways
- Conversation intelligence lifts win rates when the full automated loop closes on every call: capture, score, coach, and log.
- Five specific behaviors in 2026 benchmarks drive closed-won outcomes: talk-to-listen ratio, discovery questions, objection handling, pricing timing, and early risk signals.
- Real-time risk flagging paired with post-call coaching inside the CRM changes behavior faster than manual review or separate dashboards.
- Teams that reach 90%+ call coverage and 80%+ CRM field completion typically see 10–25% win-rate lifts within 3–6 months when coaching targets AI-flagged moments.
- See how Coffee delivers 90%+ call coverage and automatic CRM logging.
Conversation Intelligence as a Full-Funnel Coaching Engine
Most teams treat conversation intelligence as a recording library, where managers sample a handful of calls, leave comments, and move on. This sampling approach is the root problem because it captures less than 4–6% of team conversations, so feedback rests on a narrow and biased slice of rep behavior. Impressionistic feedback from that small sample rarely produces measurable behavior change across the team. True conversation intelligence solves this by running an automated cycle on every call: capture, score against proven benchmarks, surface risks in real time, deliver coaching inside the tools reps already use, and log everything to the CRM without rep effort. When any step in that cycle is manual or opt-in, the data reverts to sitting in a dashboard nobody checks.
Even a flawless capture-and-log system still needs clear behavioral targets. The loop only matters when it measures the specific actions that separate winning calls from losing ones and feeds those insights back into daily coaching.
Five Behaviors That Lift Win Rates in 2026
The table below reveals a clear pattern: winning calls rely on timing, structure, and moderation, not on talking more or asking endless questions. Both extremes, such as too few or too many questions, correlate with losses, and pricing timing influences outcomes more than pricing content.
| Behavior | 2026 Benchmark (Winning) | Common Failure Pattern | Win-Rate Impact |
|---|---|---|---|
| Talk-to-listen ratio | 43% talk / 57% listen on discovery | Talking above 65% of the call | On longer calls, lost deals average 62% rep talk time vs. 57% on won deals |
| Discovery question rate | 11–14 questions per hour-long call | Fewer than 10 or more than 16 questions | Winning calls contain 15–16 questions vs. ~20 on losing calls |
| Objection handling | Structured, specific reframe with confirmed resolution | Reps score 93/100 on listening but only 15/100 on handling | Effective objection handling correlates with higher win rates |
| Pricing and competitor mentions | Pricing introduced after problem framing, competitor mentions addressed immediately | Pricing in first 20 minutes, competitor mention left unanswered | Risk-reducing language raises win rates by 32% |
| Early risk signals | Multi-threaded with 4+ contacts, next step confirmed in-call | Single-threaded deals close at roughly 5%, while multi-threaded deals with 5+ contacts close at around 30% | Buyers who commit to a defined next step in the first three calls close at 5.6x the rate of those without one |
These benchmarks reflect how top teams already sell today, not a distant ideal. Gong Labs analysis of more than one million opportunities found teams using AI deal guidance on conversation data achieved 35% higher win rates. The loop below exists to turn these benchmarks into daily coaching inputs for every rep, on every deal.
See how Coffee scores every call against these five benchmarks automatically.
The 5-Step Automated Win-Rate Loop
The five steps below describe how Coffee turns raw calls into coaching, forecast signals, and behavior change. Each step includes a common failure point so teams can pinpoint where their current process breaks.
-
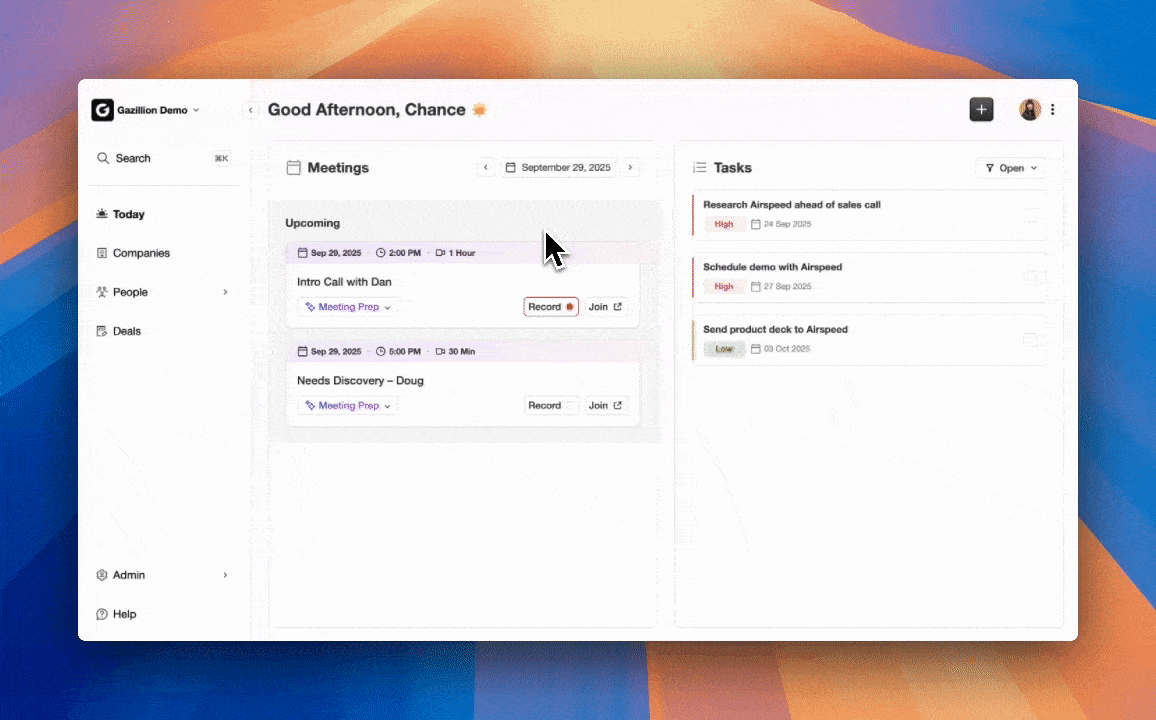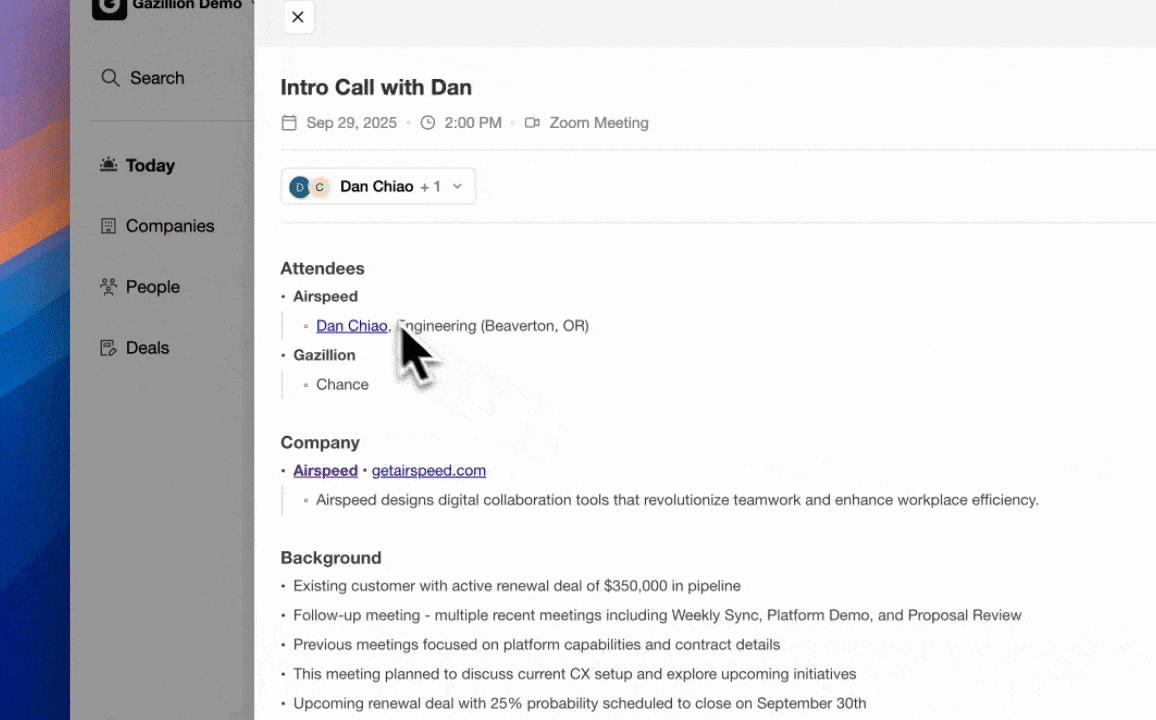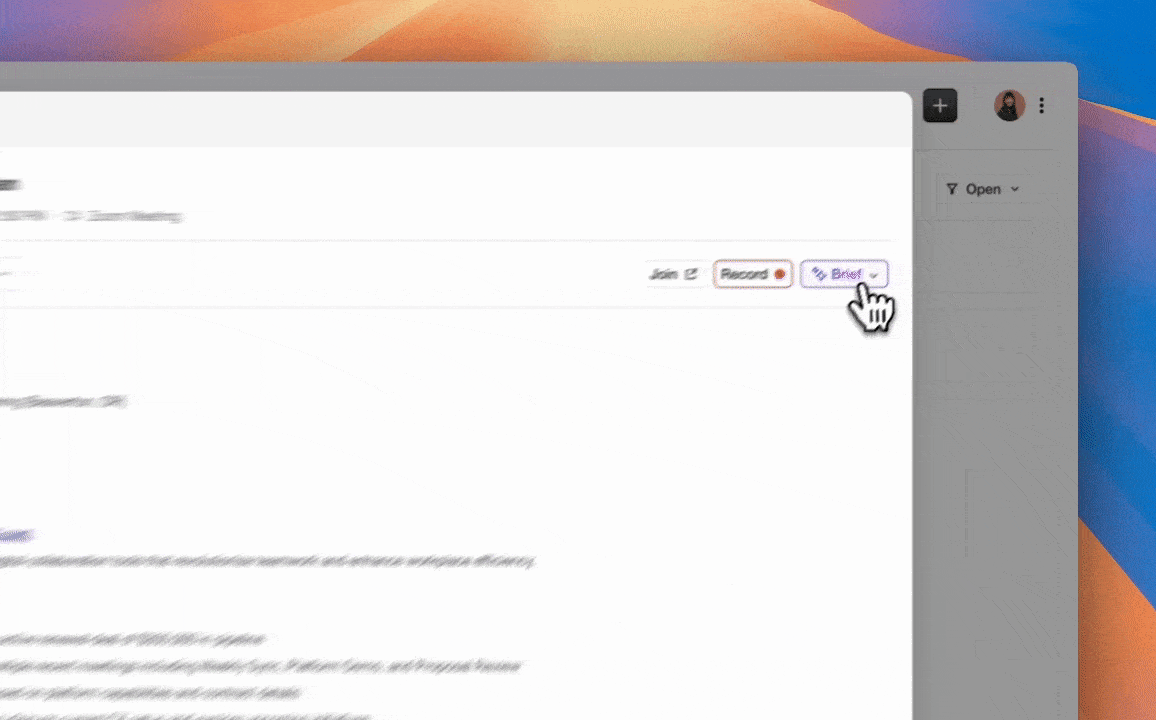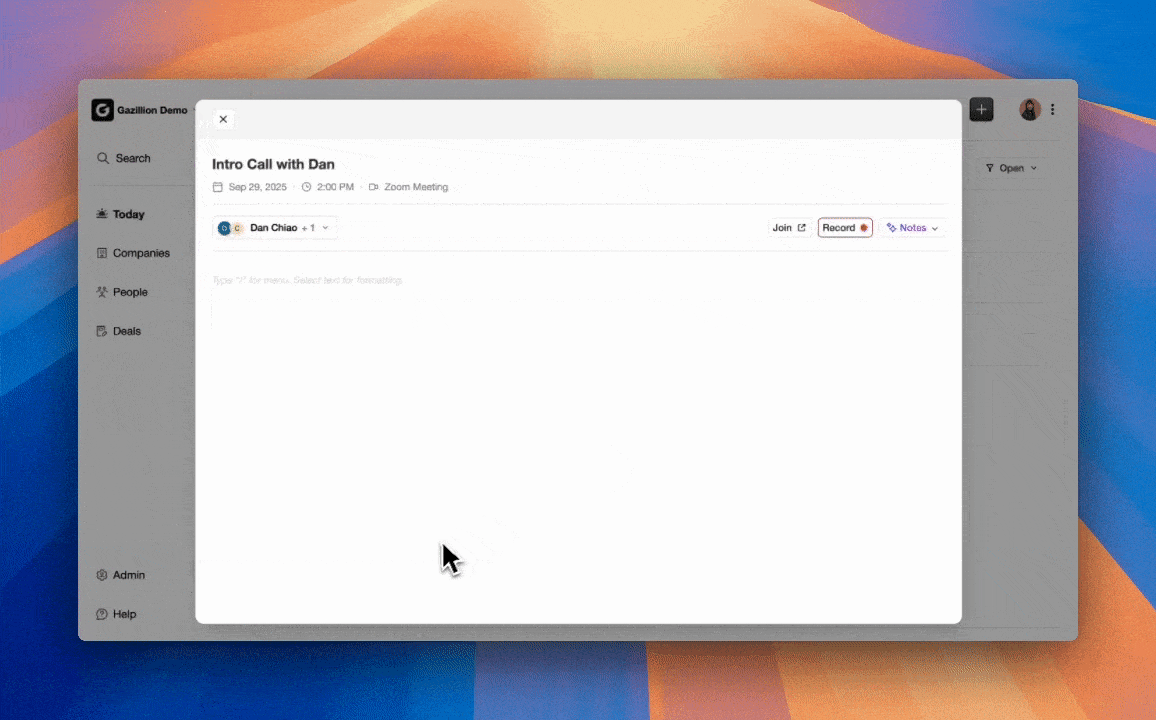
Step 1 — Automated Capture via the Coffee Agent. The Coffee AI meeting bot joins every Zoom, Teams, or Meet call automatically, records, and transcribes without rep action. Before the call, the agent delivers a briefing on attendees, roles, and prior deal context so reps enter prepared. The output is a structured transcript tied to the correct CRM record from the first second.
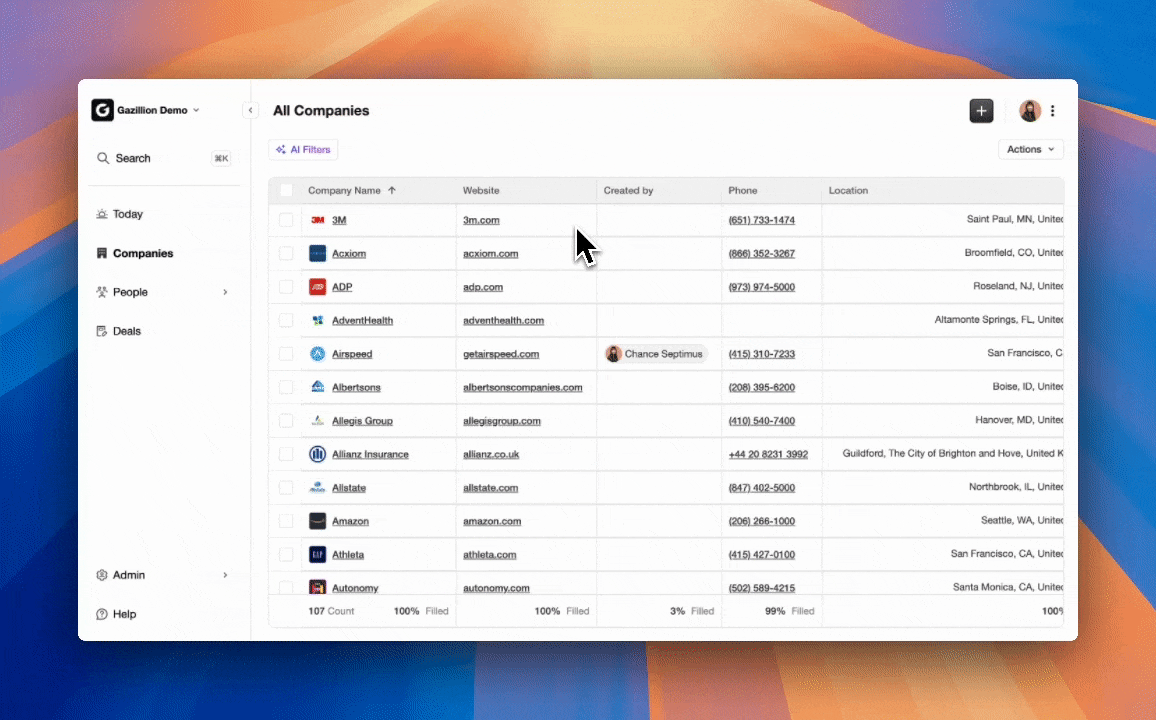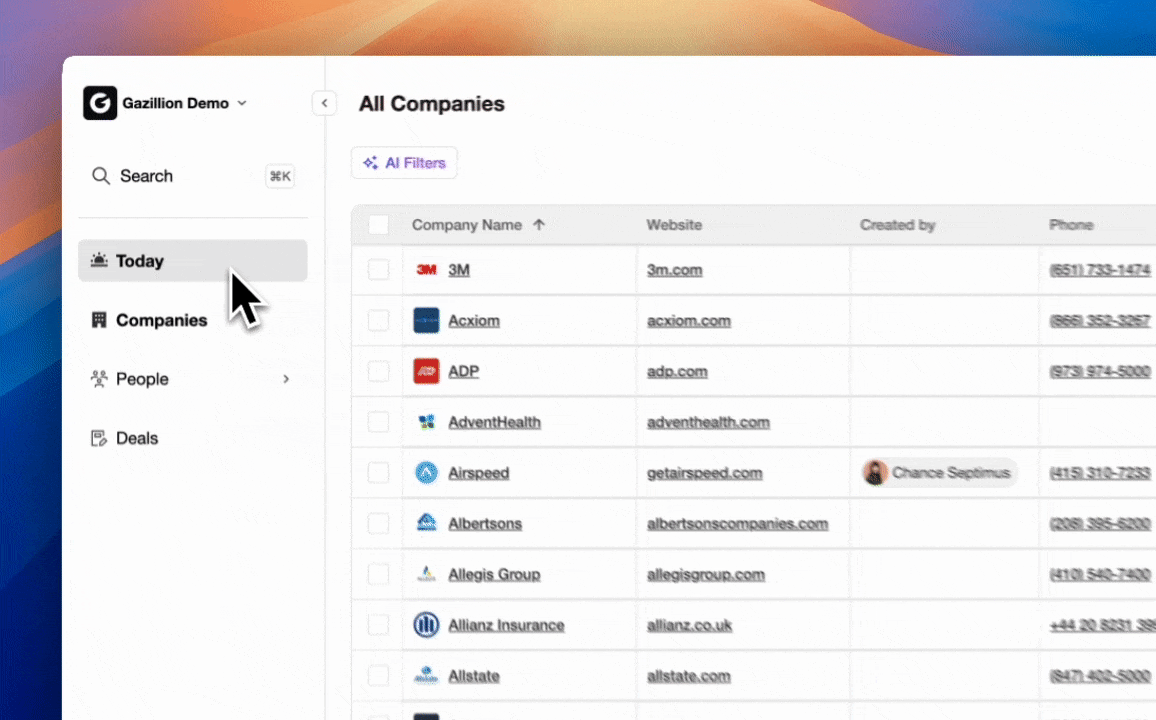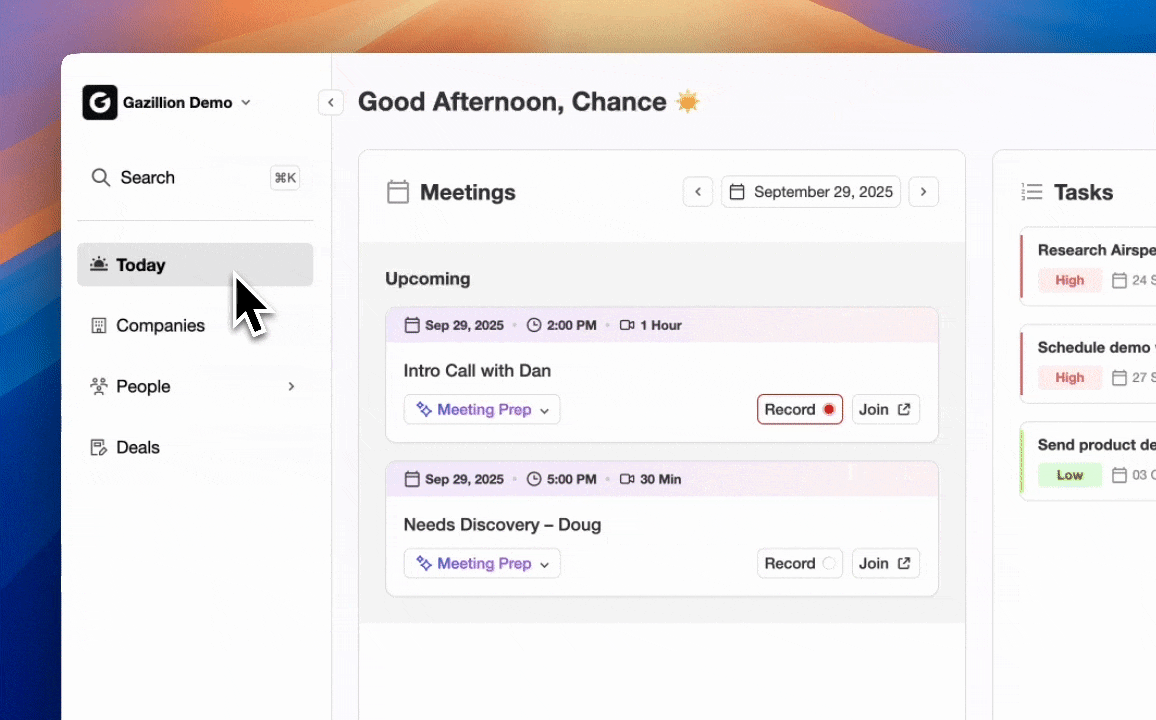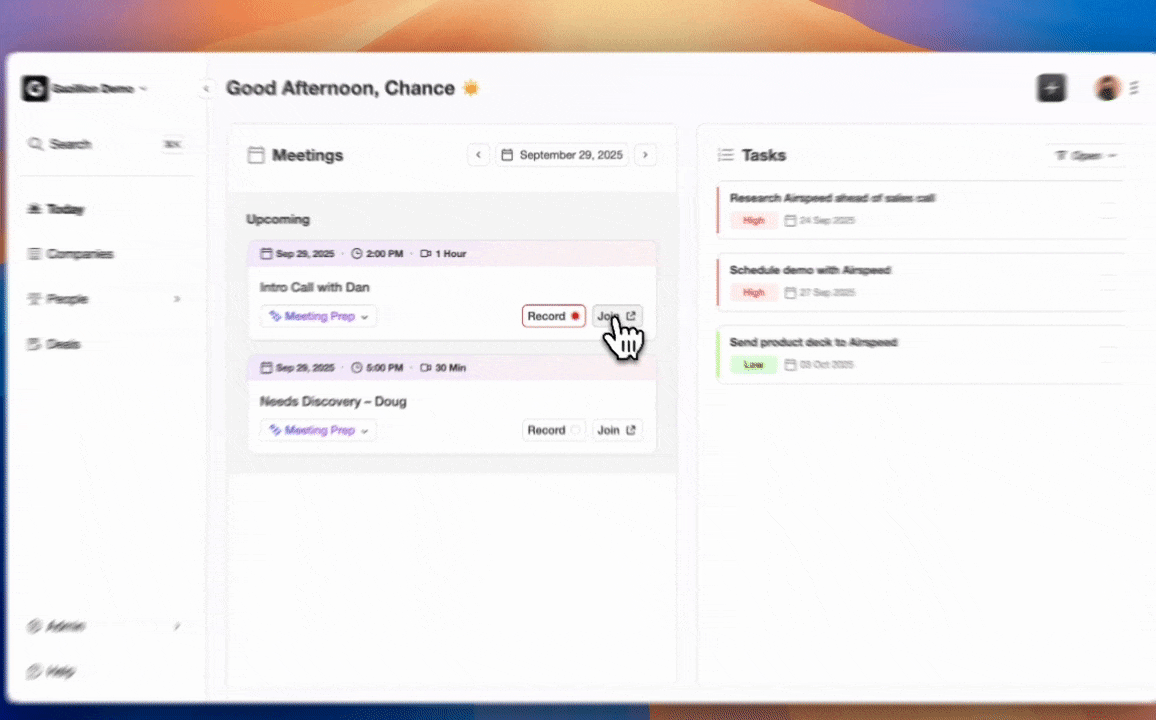
Join a meeting from the Coffee AI platform Common failure point: Sales managers review less than 5% of all sales calls when capture is manual or opt-in. Opt-in recording means the calls that most need review, such as difficult deals and struggling reps, are the ones least likely to be captured.
Step 2 — Real-Time Risk Flagging During Calls. While the call runs, the agent scores the conversation against the benchmarks in the table above. It flags competitor mentions left unanswered, talk-ratio anomalies above 75%, pricing introduced too early, and sentiment shifts from phrases like “when we move forward” to “if we move forward.” Real-time guidance inside a live meeting increases the odds of securing a clear next step because the rep receives a prompt while the deal is still active.
Common failure point: Post-call-only analysis arrives too late. AI pipeline risk detection typically identifies deal risks two to four weeks before they become visible in traditional pipeline reviews, but only when signals are read in real time, not after the call ends. Real-time flagging catches the moment, and the next step in the loop makes sure the lesson sticks.
Step 3 — Post-Call Coaching Moments Delivered Inside the CRM. Within minutes of the call ending, the Coffee agent generates a structured summary, identifies next steps, and drafts a follow-up email for rep review. Coachable moments such as missed objection handling, vague next steps, or talk-ratio drift are tagged and surfaced directly inside Salesforce or HubSpot as coaching notes, not in a separate dashboard. Formal sales coaching improves quota attainment and win rates when feedback ties to specific call moments rather than vague impressions.
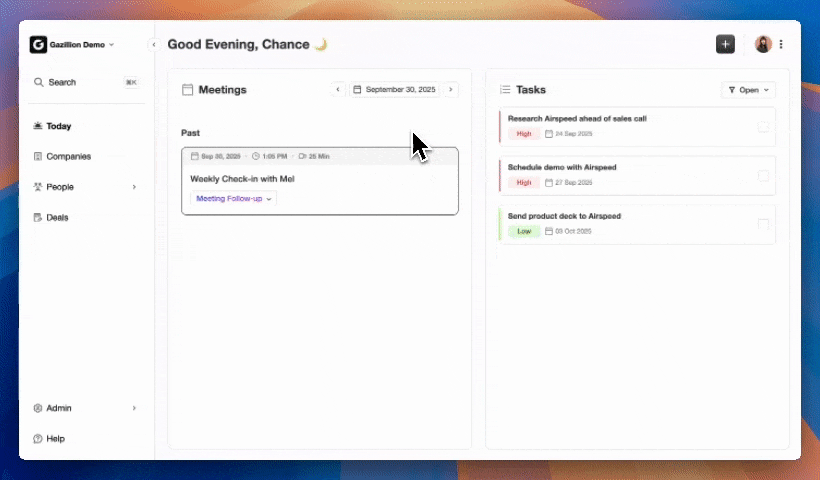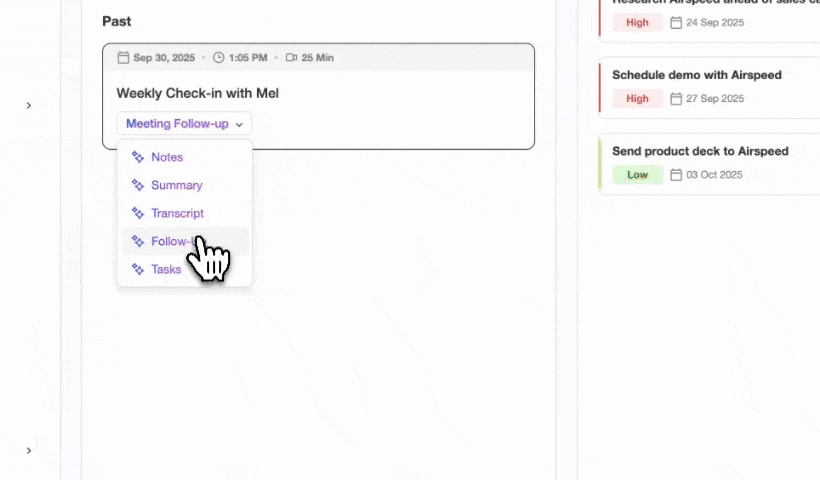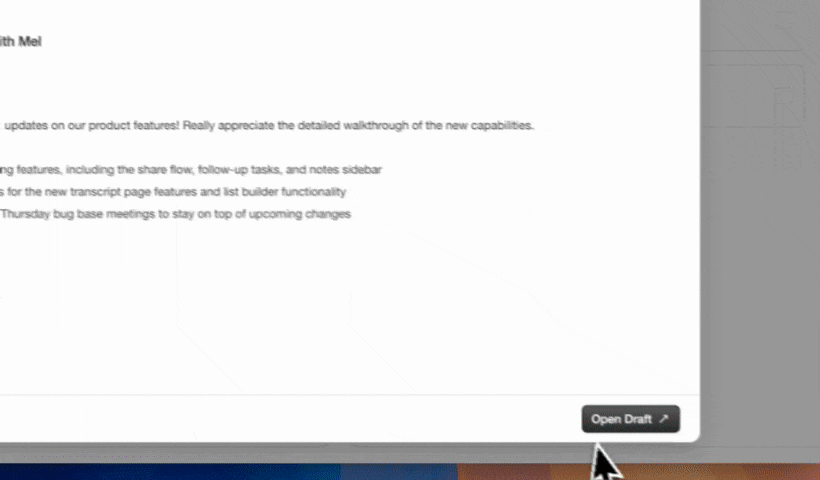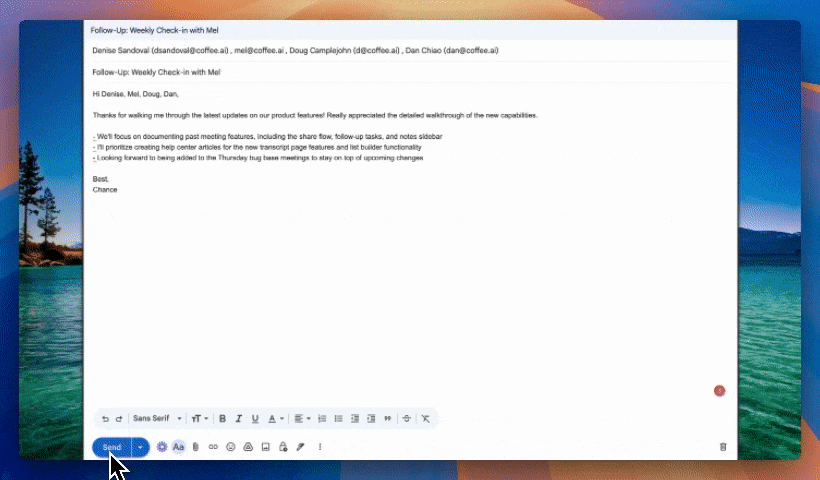
Create instant meeting follow-up emails with the Coffee AI CRM agent Common failure point: Many sales organizations that purchase conversation intelligence software never see measurable behavior change because coaching lives in a tool reps rarely open.
Step 4 — Objection-Response Libraries Pulled from Winning Transcripts. The Coffee agent indexes every closed-won transcript and surfaces the objection-handling sequences that correlate with positive outcomes. This means that when a rep faces a pricing objection or a competitive displacement question, the agent can surface the exact language top performers used in similar situations, not a generic script. That specificity helps conversation intelligence tools reduce ramp time for new SDRs and AEs by 30–85% because new reps learn from real winning behavior instead of abstract theory.
Common failure point: Sales training research shows participants forget more than 80% of curriculum-based training within 90 days. Static playbooks decay as markets shift. Libraries built from live winning calls stay current automatically because they update every time a new deal closes.
Step 5 — Automatic CRM Logging and Forecast Updates. Every call summary, action item, next step, risk flag, and MEDDIC or SPICED qualification field the agent captures is written directly to the Salesforce or HubSpot opportunity record with no rep data entry. Pipeline Compare then visualizes week-over-week changes, including progressed deals, stalled opportunities, and new additions, which replaces manual CSV exports. Teams implementing conversation intelligence typically see a 10% to 25% improvement in win rates within 3 to 6 months.
Common failure point: Teams without AI review roughly 1-3% of sales calls, while conversation intelligence raises coverage to 100%. Without AI, coverage remains in the low single digits, the same 4–6% sampling rate described earlier, so forecast data depends on rep self-reporting instead of observed deal behavior.
Scaling the Loop for Different Team Sizes and CRM Setups
The same loop can support a team of five reps or fifty, but the configuration must match CRM maturity. Teams on Salesforce with established opportunity stages, required fields, and quota hierarchies need an agent that writes to those structures precisely, not a tool that creates shadow records or breaks validation rules. Coffee’s Companion App fits this environment by authenticating against an existing Salesforce or HubSpot instance and writing enriched call data, coaching notes, and pipeline changes back to the correct records without disrupting current workflows.
Teams earlier in their CRM maturity often struggle more with adoption and data quality than with coaching content. For these teams, the Coffee agent handles contact creation, activity logging, and deal enrichment from email and calendar data before the first recorded call. The loop starts with clean data so coaching insights and forecast outputs stay reliable from day one. Explore how the Coffee Companion App layers onto your existing Salesforce or HubSpot instance without a rip-and-replace.
Automated meeting prep with Coffee AI CRM Agent Validation Checklist for Measuring Real Win-Rate Gains
Teams should confirm a few data-quality and adoption conditions before attributing win-rate movement to the loop.
- Call coverage above 90%. If fewer than 9 in 10 calls are captured, the coaching and risk signals are based on a biased sample. Opt-in recording systematically under-represents struggling reps and difficult deals, which weakens every later step in the loop.
- CRM field completion above 80%. Even with strong call coverage, coaching notes and risk flags written to incomplete records produce unreliable forecast signals. The agent should populate fields instead of waiting for reps to do it, because manual entry is the bottleneck that breaks the loop.
- Coaching cadence established. Teams running structured weekly coaching sessions built around AI call scores see a 15-25% improvement in appointment ask rate within 30 days. Without a consistent cadence, flagged moments sit in the system and never change behavior.
- Baseline win rate documented. The realistic improvement in win rates from 2026 conversation intelligence deployments falls in the 8–18% range, so teams should validate gains against a pre-deployment baseline rather than vendor case studies. The exact range and timing depend on deal cycle length and current coaching maturity.
- Lag accounted for in measurement. Win-rate improvement is a slower-moving signal that typically takes several months of call data and coaching interventions to affect closed-won outcomes. Measure stage conversion rates at 30 days as a leading indicator, and measure win rates at 90 days or later.
Frequently Asked Questions
How long does it take to set up Coffee’s conversation intelligence loop on an existing Salesforce or HubSpot instance?
Setup uses a single authentication that connects Coffee to your existing Salesforce or HubSpot instance. Once connected, the Coffee agent immediately begins scanning emails and calendars to populate and enrich existing records, and the AI meeting bot starts joining calls automatically. Most teams have the full capture, analyze, coach, and update cycle running within the same week they authenticate. Coffee does not require a rip-and-replace of existing CRM structure because it writes to the fields and objects already in place.
Who owns the coaching workflow, the sales manager, RevOps, or the agent?
The Coffee agent handles the mechanical work such as capturing calls, scoring them, tagging coachable moments, and writing summaries to CRM records. Sales managers own the coaching decisions and conversations with reps. The agent surfaces which calls need attention and why, such as a talk-ratio anomaly, a missed objection, or a competitor mention left unanswered, so managers spend their limited coaching time on the moments that matter instead of hunting for them. RevOps owns the data-quality and adoption metrics that confirm whether the loop produces reliable forecast inputs.
How quickly should a team expect to see measurable win-rate improvement?
Operational benefits such as reduced note-taking, automatic CRM logging, and pre-call briefings appear within the first few weeks. Behavioral changes in rep performance, including improved talk ratios and objection recovery rates, typically surface within 30 to 60 days when coaching ties directly to flagged call moments. Win-rate movement, which is a lagging indicator shaped by deal cycle length, usually becomes measurable at 90 days for teams with cycles under 60 days and at 120 to 180 days for longer enterprise cycles. Teams should track stage conversion rates as a leading proxy for win-rate direction during the first quarter.
Is the call data Coffee captures secure, and is it used to train AI models?
Coffee is SOC 2 Type 2 and GDPR compliant. Call transcripts, CRM records, and enrichment data are not used to train public AI models. Data processed by the Coffee agent remains within the customer’s environment and is written back only to that customer’s connected CRM instance. Teams in regulated industries should review Coffee’s security documentation directly, because heavily regulated sectors such as healthcare and finance may have requirements beyond standard SOC 2 compliance.
Conclusion: Turning Benchmarks into Daily Execution
The gap between knowing that specific talk ratios, question counts, and pricing timing win deals and coaching every rep to those standards is an execution problem, not a knowledge problem. Legacy conversation intelligence tools stop at the recording and produce dashboards that demand manual review, coaching that depends on manager availability, and CRM updates that depend on rep discipline. Those dependencies do not scale across hundreds of calls each week.
The five-step loop solves the execution gap by removing manual work at every stage. Capture runs automatically on nearly every call, real-time risk flags and post-call coaching appear inside the CRM where reps already work, and forecast data updates without rep effort. When the loop closes on more than 90% of calls, the behavioral benchmarks in the table above shift from aspirational targets to operational standards for the entire team.