Written by: Doug Camplejohn, CEO & Co-Founder, Coffee | Last updated: September 13, 2026
Key Takeaways
- Define a canonical schema and field-level data dictionary so every field has clear definitions, allowed values, formats, and ownership before cleanup starts.
- Use a missing-data hierarchy to triage blanks by business impact. Fill critical fields that affect routing, forecasting, or reporting before important or optional fields.
- Apply concrete normalization rules for validity defects. Standardize company names, phone numbers to E.164, dates to ISO 8601, and enforce picklist values at entry.
- Enrich only genuine gaps and record source, timestamp, and confidence for every appended value so reps and scoring models can trust the data.
- Replace manual entry with an autonomous agent that standardizes, enriches, and unifies records automatically, so good data keeps flowing in and out without rep effort.
The Missing-Data Hierarchy: Triage Blanks By Business Impact
Incomplete CRM data is primarily a triage problem. 43% of sales forecasts miss their target by 10% or more, and the root cause is incomplete input data rather than a flawed forecasting model. Teams burn sprint capacity enriching optional fields while critical blanks silently break lead routing and forecast rollups.
The decision rule is simple. For each blank field, ask whether the field affects routing, forecasting, or reporting. That answer determines the tier.
Critical fields directly affect routing, forecasting, or reporting. These fields matter because each one feeds a different downstream system. Without an opportunity owner, no rep is accountable for the deal. Without a deal stage, the record drops out of stage-weighted forecasts entirely. Without an amount or close date, pipeline coverage ratios are computed on corrupted inputs, so the forecast looks healthy while the underlying data is not. Organizations that had not conducted a formal data quality audit in the prior two quarters showed field completeness of 75–85% alongside structural pipeline credibility of only 50–65%, a gap invisible to standard dashboard metrics. Critical fields include opportunity owner, deal stage, amount, close date, and primary contact.
Important fields affect segmentation and prioritization but do not break a forecast rollup if blank. A missing industry classification degrades lead scoring and territory assignment. A missing company size prevents accurate ICP matching. A missing buying-group role such as economic buyer, technical evaluator, or champion leaves deal risk unassessed. A contact record without a buying-group role and a business-unit or account attachment is barely more useful than a business card. Important fields include industry, company size, buying-group role, and lead source.
Optional fields have no pipeline impact. LinkedIn URL, secondary phone, and fax number belong here. Mark them Unknown rather than spending enrichment credits on them. According to the DAMA framework as explained by Data Workers, nullability rules should vary by column. Optional fields are supposed to be null while required fields must not be, and a blanket “no nulls anywhere” rule generates false alarms and teaches analysts to ignore alerts.
The cost of getting triage wrong is measurable. Incomplete lead profiles break routing rules and inconsistent field values cause incorrect territory assignments, directly linking missing CRM fields to misrouted and lost revenue. For a team generating $10M in annual pipeline, a 15% leakage rate represents $1.5M in recoverable revenue lost to operational failure rather than competitive loss.
How To Build A CRM Data Dictionary For Sales Records
A CRM data dictionary is the single artifact that makes standardization repeatable across teams, quarters, and headcount changes. It is also the one artifact that no competitor content publishes at field level. Without it, every new hire, every integration, and every import re-introduces the same format variants the last cleanup removed.
The table below shows how four core fields translate into dictionary entries. Notice that each row answers the same three questions: what the field means, what values are allowed, and whether a blank counts as a defect.
| Field | Definition | Allowed Values / Format | Required? |
|---|---|---|---|
| Country | Billing country of the account | ISO 3166 full name: “United States” (not “USA,” “US,” or “U.S.A.”) | Yes |
| Industry | Primary operating industry of the account | Picklist: “Software” (not “SaaS,” “Tech,” or “IT”) | Yes |
| Employees | Headcount band of the account | Numeric band (e.g., 50–200); blank → “Unknown” + enrichment candidate | No |
| Opportunity Owner | Assigned sales rep responsible for the deal | Active user lookup; no free-text entry | Yes |
Three additional dictionary columns belong in prose rather than the table to keep it scannable. Source records where the value originates, such as rep entry, enrichment provider, or integration, so a scoring model or a rep can assess its reliability. Owner names the data steward accountable for maintaining the field’s standards and resolving exceptions; the DAMA-DMBOK framework assigns data quality responsibility to domain experts with authority to fix upstream issues. Refresh frequency sets the cadence for re-enrichment. Job titles change quarterly, company headcount changes annually, and close dates should be validated at every pipeline review.
The “Required?” column is the dictionary’s most important field. The DAMA-DMBOK framework treats completeness as whether required values are present. A missing value in a required field is a completeness defect, not an accuracy defect. That distinction is why the required-versus-optional split drives the entire triage hierarchy above. ISO/IEC 25012 defines completeness as “the degree to which subject data associated with an entity has values for all expected attributes,” separating missing attributes from contradictions or format errors.
Normalization Rules With Before/After Examples
Normalization is the remediation workflow for validity defects, where values are present but violate format, range, or business rules. The DAMA-DMBOK 2.0 framework distinguishes a missing value, which is a completeness defect, from an invalid value, which is a validity defect. A phone number can be present and still fail E.164, which requires a different remediation path than a blank field. The rules below are written so you can copy them directly into your own schema.
Company names: “Acme Inc.” / “Acme, Inc.” / “ACME” → “Acme Inc.” Store the canonical legal name and strip trailing punctuation variants. Fuzzy matching tools using Levenshtein or Jaro-Winkler algorithms can surface near-duplicates for human review before merge.
Phone numbers: All formats → E.164: “+15551234567.” Strip parentheses, dashes, spaces, and country-code variants at ingestion. A phone number stored as “(555) 123-4567” is a validity defect even though the field is populated.
Dates: All formats → ISO 8601: “2026-09-13.” This eliminates the MM/DD/YYYY versus DD/MM/YYYY ambiguity that corrupts close-date forecasting across international teams.
Job titles: Standardize to a controlled picklist such as “VP of Sales,” not “VP Sales,” “Vice President, Sales,” or “Sales VP.” Store the vendor-provided raw title in a separate text field so the original value is preserved for reference without polluting the normalized field used in routing and scoring.
Picklists: Enforce allowed values at the field level and reject free-text entry. A training dataset for a classification model had 47 distinct values in a product category field while the official catalogue defined only 12. The 35 extra values were typos, encoding errors, and deprecated categories that the model learned as distinct categories, which reduced its ability to generalize. The same failure mode applies to CRM picklists used in lead scoring and territory assignment.
Note the distinction between a missing value and an invalid value, because they require separate remediation workflows. Completeness issues are recoverable by filling empty fields. Validity issues mean values are present but wrong and require correction against domain rules, which calls for a different control, a different owner, and a different KPI.
Enrichment With Provenance: Source, Timestamp, Confidence
Enrichment should verify rep-entered data before writing over it. The trust gap that causes teams to distrust enriched values and revert to manual entry comes down to one missing ingredient: provenance. Without a recorded source, timestamp, and confidence level, neither a rep nor a scoring model can tell whether a field is current fact or six-month-old guesswork. Provenance and freshness metadata are not optional extras. Without them, neither a scoring model, a sales rep, nor an AI research tool can tell whether a field is current fact or six-month-old guesswork.
The recommended write policy is “fill-only unless flagged.” Enrichment populates a field only when it is blank, or an admin sets an override flag for selective re-enrichment. Storing provenance at minimum as three attributes, the enrichment source, the last enriched date, and whether the last write was fill-only or overwritten, enables teams to roll back a bad mapping, isolate a bad batch, and explain why a value changed on a specific day.
Every enriched value needs three things recorded at the moment it is written: where it came from, when it was last verified, and whether the write replaced an existing value or filled a blank. Provenance recorded at the point of capture is far more reliable than provenance reconstructed after the fact.
Quality states should be distinguished instead of collapsed into a binary flag. Distinguishing quality states such as verified, candidate, or disputed is a stronger model than a simple yes/no verification flag. A verified value has been confirmed against an authoritative source. A candidate value has been appended from a provider but not independently confirmed. A disputed value has conflicting claims from multiple sources. Never silently blend low-confidence candidate values with verified ones in the same field. Low-confidence fields should be visibly flagged in the CRM and never silently blended in with verified ones.
Refresh cadence should be driven by field-level volatility, not a blanket annual re-run. Job titles change, companies get acquired, and contacts leave. A field-specific service objective, such as quarterly for job title and annually for company headcount, keeps enrichment current without unnecessary provider costs.
Standardize At Entry Across All Sources
Data entry problems originate at every ingestion point, including web forms, CSV imports, integrations, and manual rep entry. Fixing records after the fact is always more expensive than preventing bad values at the source. Automating email and calendar capture can eliminate 60–70% of manual data entry for sales teams, which creates the highest-leverage entry-point control available.
Platform mechanics vary by CRM and must be configured explicitly rather than assumed.
In Salesforce, validation rules enforce field-level business logic at save time. For example, they can reject a close date in the past for an open opportunity or require Amount to be populated before a deal can advance past “Proposal.” Required-field enforcement prevents records from being saved without critical values. These controls apply to UI entry, API writes, and import operations.
In HubSpot, required properties prevent records from being saved without specified fields. Custom duplicate detection rules (available on Data Hub Professional or Enterprise) allow up to two rules per object and up to nine properties for comparison, which enables domain-specific duplicate definitions rather than relying on HubSpot’s default field comparisons alone.
In Dynamics 365 Customer Insights, records are only imported if all required fields are mapped and data exists in each mapped source column. Failed records must be exported, corrected, and re-imported. The system does not automatically repair incomplete records. This strict ingestion behavior means malformed or incomplete records are quarantined rather than silently admitted. It also requires a defined correction path so failed records do not disappear into an unmonitored error log.
The tradeoff is explicit. Strict ingestion rules that reject malformed values will leave target tables incomplete unless every rejected record lands in a quarantine queue with a defined correction path. The quarantine queue is not a failure. It is the control that makes bad data visible and recoverable rather than invisible and compounding.
Can ChatGPT Clean CRM Data And Where It Breaks
AI-assisted cleaning helps with specific, bounded tasks and fails, sometimes silently and dangerously, on others. The practical answer is that ChatGPT can clean CRM data partially, with significant caveats that most tutorials omit.
The useful way to think about AI cleaning is to separate tasks where the correct output is deterministic from tasks that require factual accuracy. The first category is safe to automate, and the second is where silent errors enter production CRM data.
Where AI-assisted cleaning helps:
- Normalization of text fields where the correct output is deterministic, such as standardizing country names to ISO 3166 format
- Deduplication candidate generation that flags pairs for human review rather than merging automatically
- Pattern detection and anomaly flagging across large record sets
- Drafting normalization rules from sample data
Where it fails:
- Inventing missing values with no source attribution or audit trail
- Mishandling numeric strings. ZIP code “01002” looks like the number 1,002 to the model, which “corrects” it, and product SKU “00456” becomes “456,” introducing errors the messy version did not have
- Over-aggressive deduplication where “John Smith, 123 Main St” and “John Smith, 456 Oak Ave” may be merged despite being two different people
- Domain-specific duplicate definitions that the model cannot infer unless you specify rules such as “same email + same phone + transaction within 30 days”
A 2025 study on AI-assisted data cleaning found that fully automated AI cleaning with no human review introduced errors in 8–15% of cases depending on data type. That error rate is too high for production CRM data driving routing, forecasting, and compensation.
There is also a distinction between two failure modes that share the name “hallucination.” A true hallucination is where the model invents something with no source in the data. A “wrong-but-faithful” answer is where the model reads a record correctly and repeats a fact that happens to be false, such as a stale renewal date or a duplicate contact. Wrong-but-faithful answers are more dangerous in production because they sound perfect and are internally consistent with a real record, so they sail past human review. The Alansari and Luqman 2026 survey in Computer Science Review confirms that hallucination risk originates at multiple stages of model development and deployment, and no single mitigation method fully eliminates it.
The rule is simple. AI should never guess missing sales information. It should flag gaps for human review or structured enrichment with provenance. Use it to surface candidates, not to write facts.
The Recurring Quality Loop: What To Monitor
A one-time cleanup without a recurring quality loop produces a clean dataset that decays. CRM data quality degrades approximately 30% per year, and this degradation is non-linear. It accelerates as the volume of unresolved records grows, compounding across planning cycles. Whatever tools you use, the work does not end at cleanup.
Four KPIs belong in every quality review:
- Completeness % — percentage of required fields populated, measured per critical field and per segment, not just globally
- Duplicate rate — percentage of records representing the same real-world entity more than once; a CRM duplicate rate above 5% is a warning sign of data quality problems that contribute to funnel leakage
- Invalid-value rate — percentage of populated fields that fail format, range, or domain rules
- Stale-record % — percentage of open opportunities with no logged activity in 30+ days or close dates that have passed without stage movement
Completeness must be measured per segment. A 2% null rate across a million records can look healthy while that 2% represents 80% of one region, so clustered missing data hides in the average. Run completeness by region, by team, and by deal stage to surface the real distribution.
Cadence should follow business impact. Run monthly reviews for critical fields such as owner, stage, amount, and close date, and quarterly reviews for the full record set. Each data quality dimension needs a different control. A single quality score hides different problems. Data can arrive on time and still be stale, or be current and still miss required fields. Completeness, validity, uniqueness, and timeliness are separate metrics requiring separate remediation workflows and separate owners.
How Coffee Standardizes Incomplete Sales Records Automatically
Every method described above depends on humans enforcing standards at entry. That dependency is the structural flaw. 37% of sales reps admit to fabricating data to clear mandatory fields when under quota pressure, and 79% of opportunity data that sales reps collect never makes it into the CRM. Manual entry will always reintroduce the problem that manual cleanup just solved. The next step is removing that dependency at the system level.
Coffee’s autonomous agent removes the need for human data entry by handling data entry, enrichment, and unification automatically. This approach ensures that good data goes in so good data comes out.

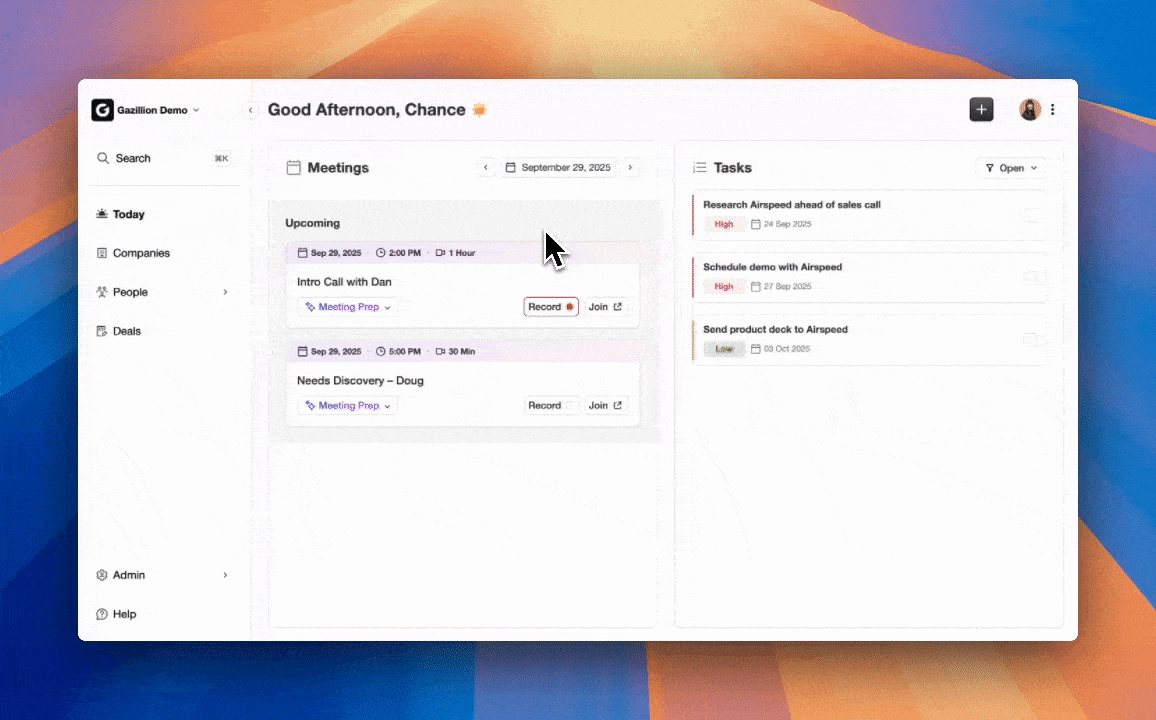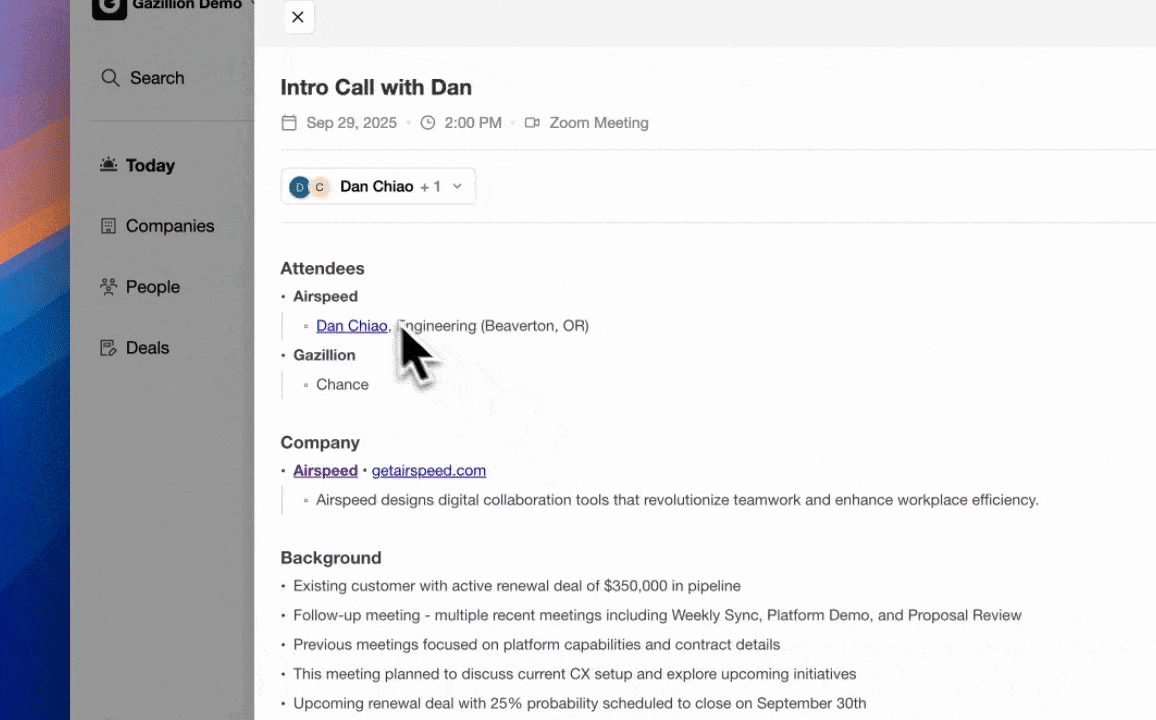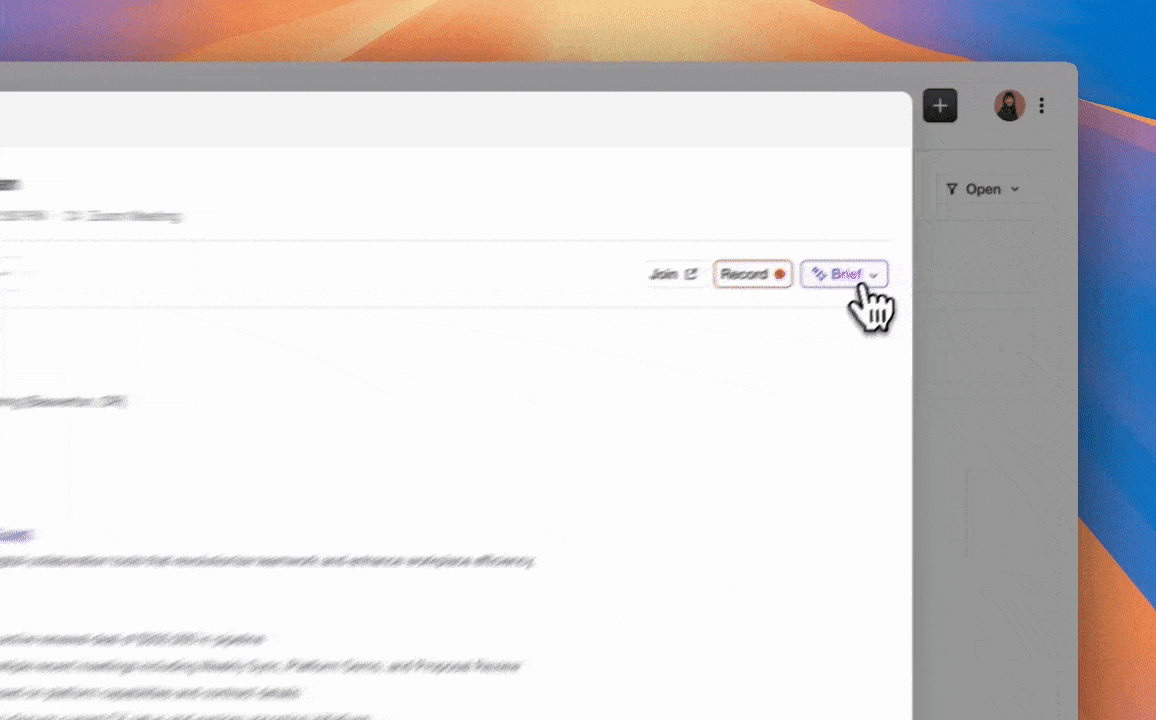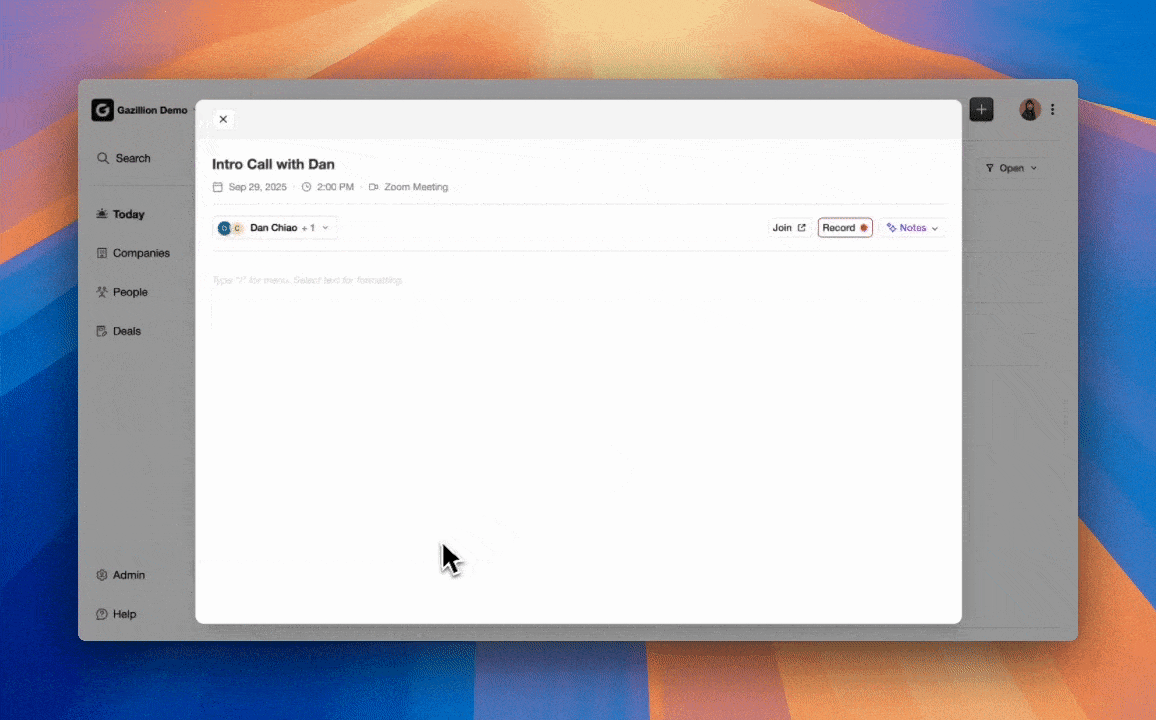
- Auto-create contacts and companies from email and calendar so every interaction is captured and associated with the correct record without rep effort
- Data enrichment via licensed partners with provenance, including source, timestamp, and confidence, recorded on every appended value
- Activity logging that keeps deal state current autonomously and reduces stale-record decay
- Meeting briefings and automated summaries that structure qualification data such as BANT, MEDDIC, and SPICED consistently into the CRM after every call
- Pipeline intelligence with the Compare feature, which visualizes week-over-week changes and highlights stalled opportunities without manual CSV exports
- Visitor identification that turns anonymous website traffic into named, enriched leads ready for outreach
Coffee operates in two modes: as a standalone AI-first CRM for SMBs, or as a companion app on top of an existing Salesforce or HubSpot instance. In both cases the agent handles the data-in process, which keeps the system of record accurate without rep effort. The practical result is 8–12 hours per rep per week returned from data entry and post-meeting administration.
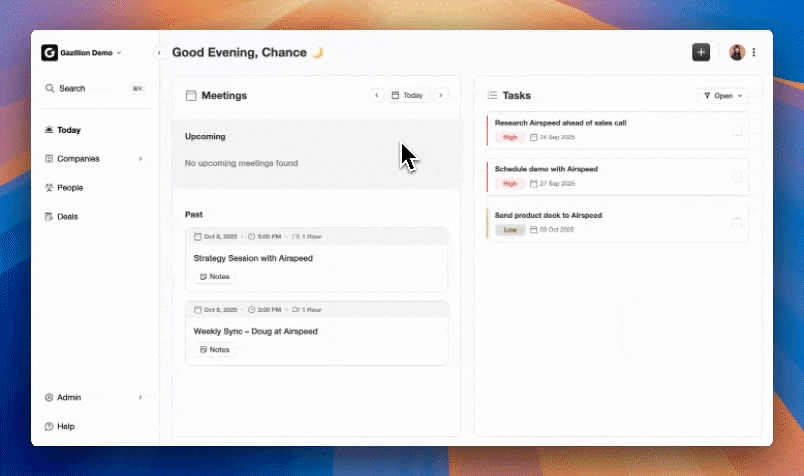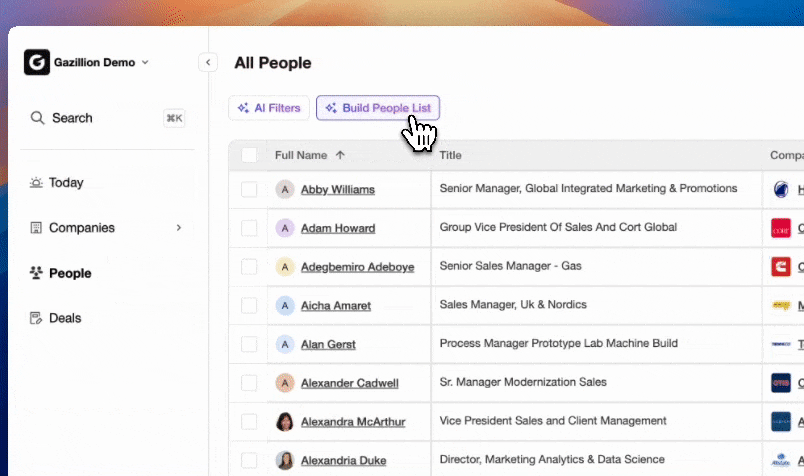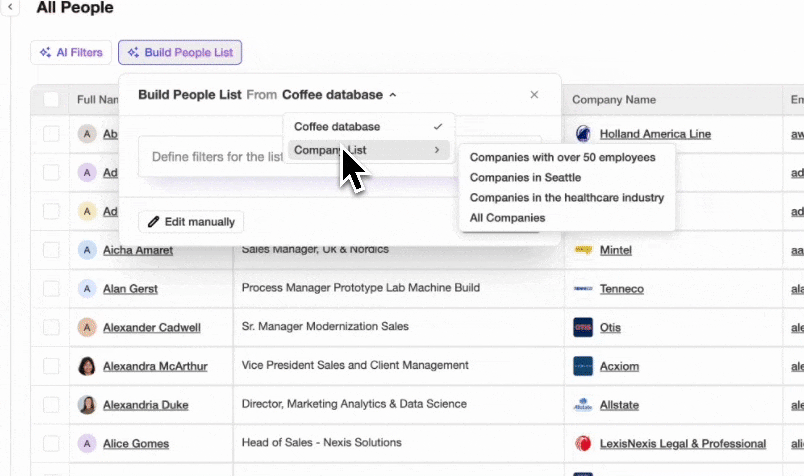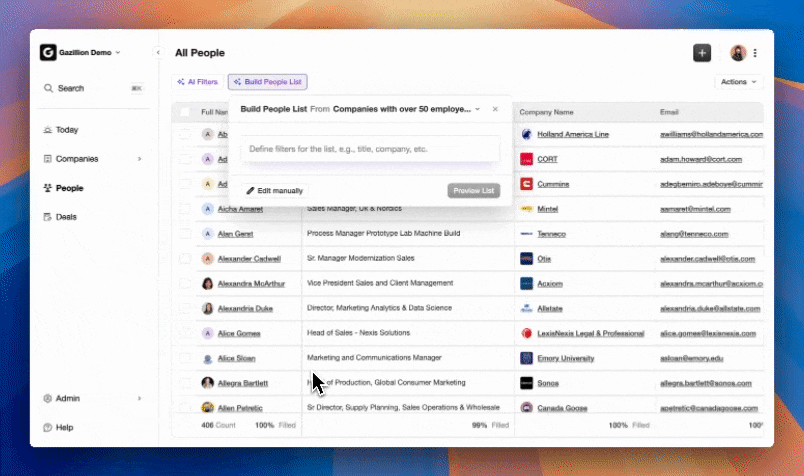
The comparison below shows where the manual-entry and standalone-enrichment approaches leave gaps that Coffee closes. The pattern to notice is that legacy tools depend on rep effort, enrichment tools append without context, and only Coffee handles capture, provenance, and unification in one system.
| Attribute | Legacy CRM (Manual Entry) | Standalone Enrichment Tool | Coffee |
|---|---|---|---|
| Data entry | Manual rep entry; no automated capture | No capture; appends to existing records only | Automated capture from email and calendar; no rep input required |
| Enrichment provenance | None; rep-entered values carry no source, timestamp, or confidence metadata | Varies by provider; many return opaque results with no field-level source or confidence rating | Licensed partner enrichment with source, last enriched date, and write type recorded per field |
| Unification | Fragmented across CRM, email, call tools, and spreadsheets, with no single coherent view | Appends to CRM records but does not unify unstructured data such as emails and transcripts with structured fields | Unified structured and unstructured data, including emails, call transcripts, and calendar events, into one coherent record in a built-in data warehouse |
Replace manual data entry with an autonomous agent and let Coffee standardize, enrich, and unify your CRM records automatically.
Frequently Asked Questions
What Is The Difference Between CRM Data Standardization And Enrichment?
Standardization defines the canonical schema and normalizes existing values to conform to it. For example, it ensures every Country field contains the ISO 3166 full name rather than an abbreviation. Enrichment appends new information from external sources to fill gaps that standardization cannot address, such as adding a missing job title or company headcount from a licensed data provider. Standardization must come first. Records for “IBM Corp” and “International Business Machines” will not match without it, and enrichment appended to unmatched records attaches correct data to the wrong account. The DAMA-DMBOK framework treats these as separate data quality disciplines. Standardization addresses validity and consistency defects, while enrichment addresses completeness defects in required fields.
How Do I Decide Which Blank Fields To Enrich?
Apply the missing-data hierarchy from earlier and enrich critical blanks first, since those are the fields that affect routing, forecasting, and reporting. A missing owner causes duplicate follow-up, and a missing close date corrupts pipeline coverage ratios. Next, enrich important fields that affect segmentation and prioritization such as industry, company size, and buying-group role. For optional fields such as LinkedIn URL, secondary phone, and fax, mark them Unknown rather than spending enrichment credits on them. The decision rule for every blank is whether the field affects routing, forecasting, or reporting. If it does, treat it as critical and fill it. If it does not, assess whether it affects segmentation before deciding whether to enrich or mark Unknown.
Can ChatGPT Clean CRM Data?
ChatGPT and similar large language models can help partially. They work well for normalization of text fields where the correct output is deterministic, deduplication candidate generation for human review, and anomaly flagging across record sets. They fail on tasks that require factual accuracy without a verified source. They invent missing values, provide no source attribution, and leave no audit trail. Numeric strings are a specific failure mode. ZIP code “01002” gets “corrected” to “1002” because the model treats leading zeros as formatting errors. The 2025 study cited earlier found that fully automated AI cleaning introduced errors in 8–15% of cases, which is too high for production CRM data. The rule for CRM data is that AI should flag gaps for human review or structured enrichment with provenance and never guess missing sales information.
What Is A CRM Data Dictionary?
A CRM data dictionary is a field-level reference document that defines, for every field in the CRM schema:
- Definition — what the field means
- Allowed values or format — the canonical form values must take
- Required status — whether a blank is a completeness defect
- Source — where the value originates
- Owner — the data steward accountable for the field’s standards
- Refresh frequency — how often the value should be re-verified or re-enriched
It is the artifact that makes standardization repeatable across teams, quarters, and headcount changes. Without a data dictionary, every new hire and every new integration re-introduces the same format variants the last cleanup removed. The DAMA-DMBOK framework treats the data dictionary as a core metadata management deliverable and recommends assigning an owner to every tier-1 field as part of the governance rollout.
How Often Should I Audit CRM Data Quality?
Run monthly audits for critical fields such as opportunity owner, deal stage, amount, and close date, because these fields drive weekly pipeline reviews and monthly forecast commits. Run quarterly audits for the full record set, measuring completeness %, duplicate rate, invalid-value rate, and stale-record % per segment. Measuring globally rather than per segment hides clustered problems, and the 2% null rate example above is the classic case. Each data quality dimension requires a separate control and a separate owner. Completeness, validity, uniqueness, and timeliness are not interchangeable metrics and cannot be collapsed into a single quality score without hiding the specific failure modes that require different remediation workflows.
Conclusion: Stop Cleaning And Start Standardizing
Incomplete CRM data is a triage and governance problem, not a cleanup problem. Teams that treat it as cleanup spend sprint capacity enriching optional fields while critical blanks silently break lead routing and forecast rollups. They then repeat the cycle because manual rep entry reintroduces the same gaps the cleanup just removed. The method above, which combines a canonical schema, missing-data hierarchy, copyable normalization rules, provenance-tracked enrichment, entry-point enforcement, and a recurring quality loop, addresses the structural cause rather than the symptom.
The definitive solution is removing the human data entry dependency entirely. Coffee’s autonomous agent captures contacts, companies, and activities from email and calendar, enriches records via licensed partners with source, timestamp, and confidence recorded per field, unifies structured and unstructured data into a single coherent view, and keeps deal state current without rep effort. Whether deployed as a standalone AI-first CRM or as a companion app on top of Salesforce or HubSpot, Coffee ensures that good data goes in so good data comes out and that the data entry problem is solved at the source rather than cleaned up after the fact.
Start with Coffee and let an autonomous agent standardize, enrich, and unify your CRM records automatically so your next forecast is built on verified facts.